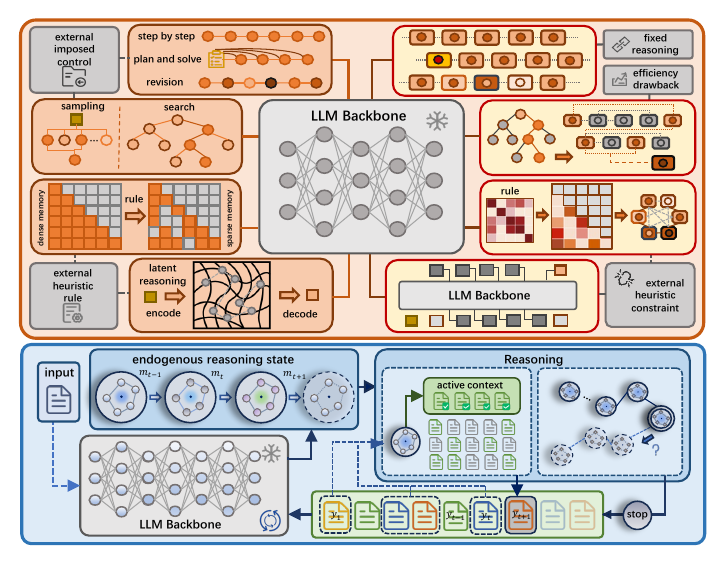
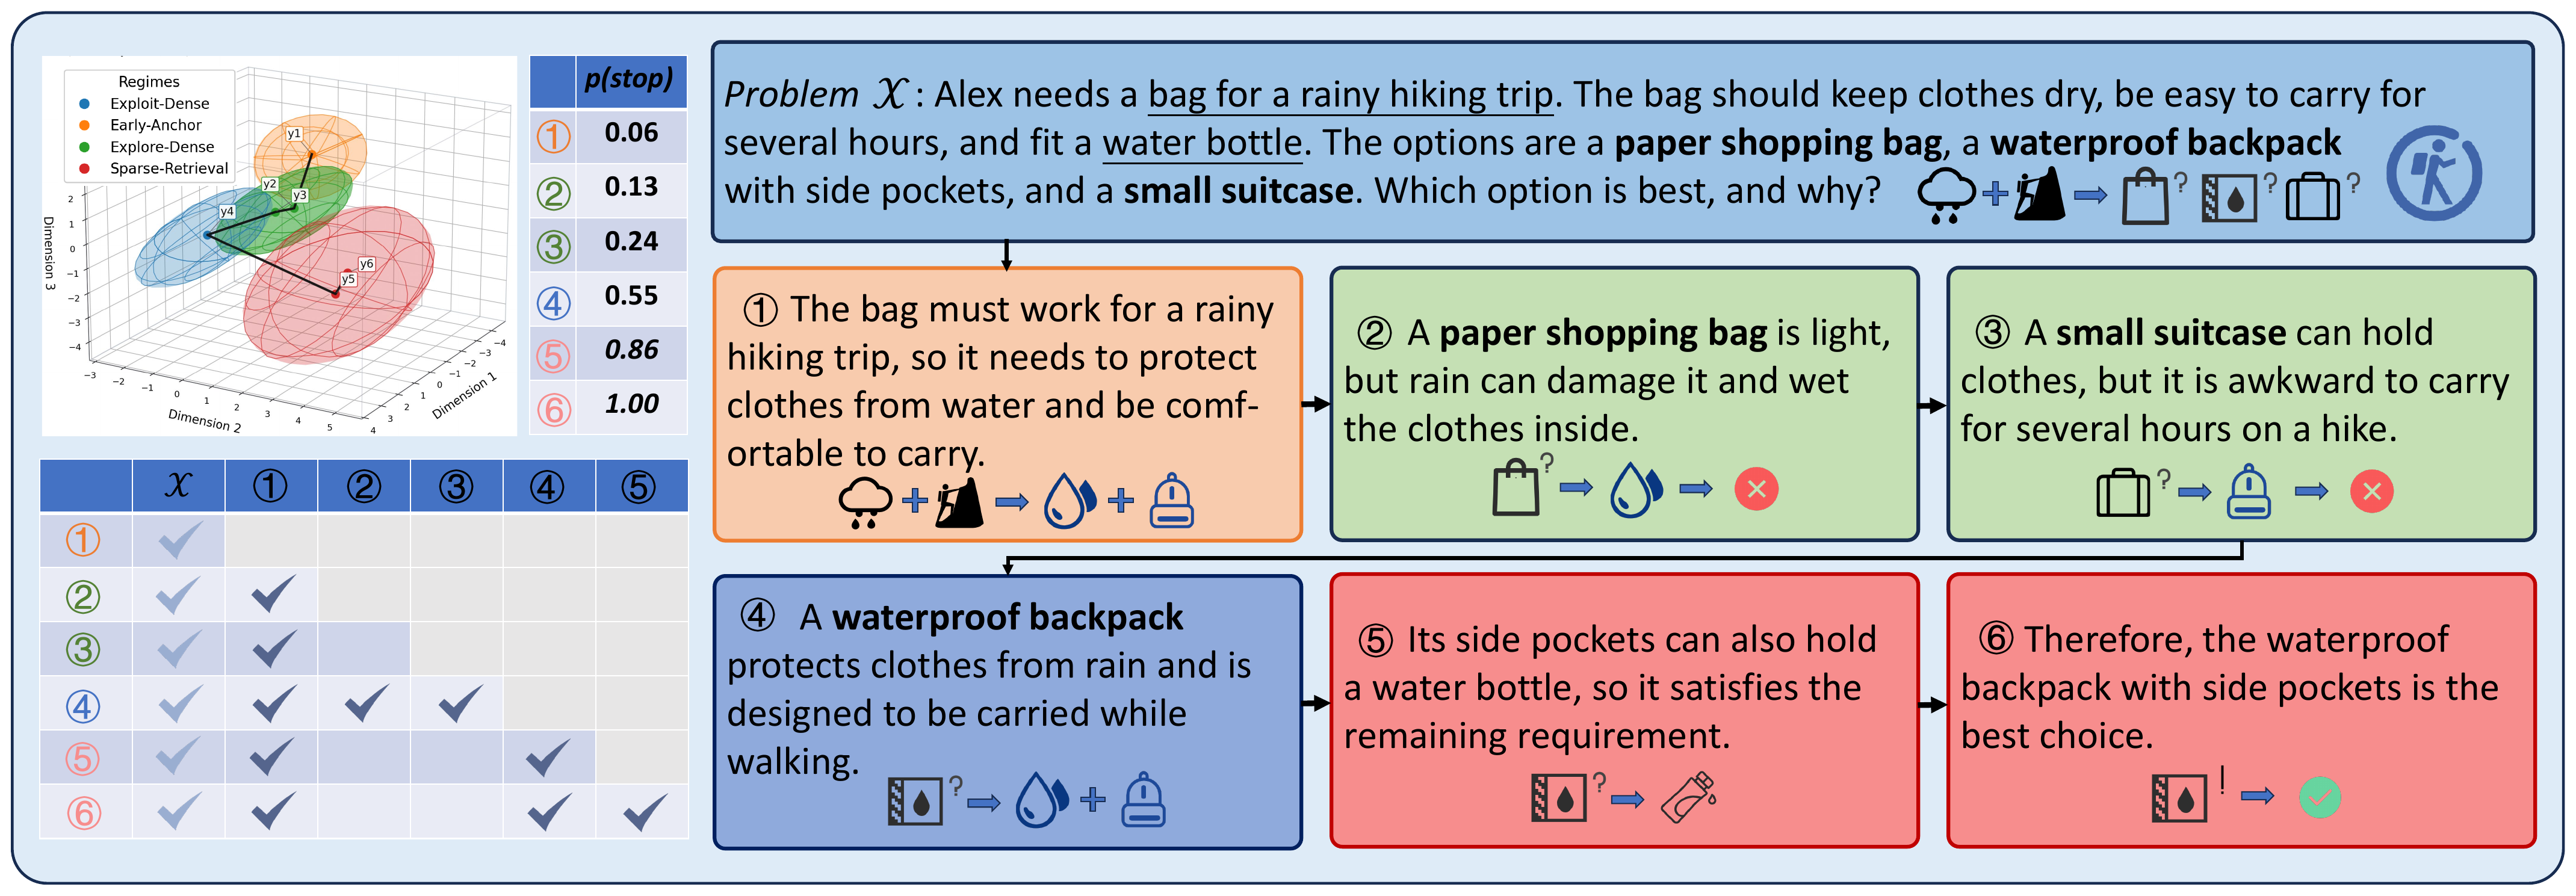
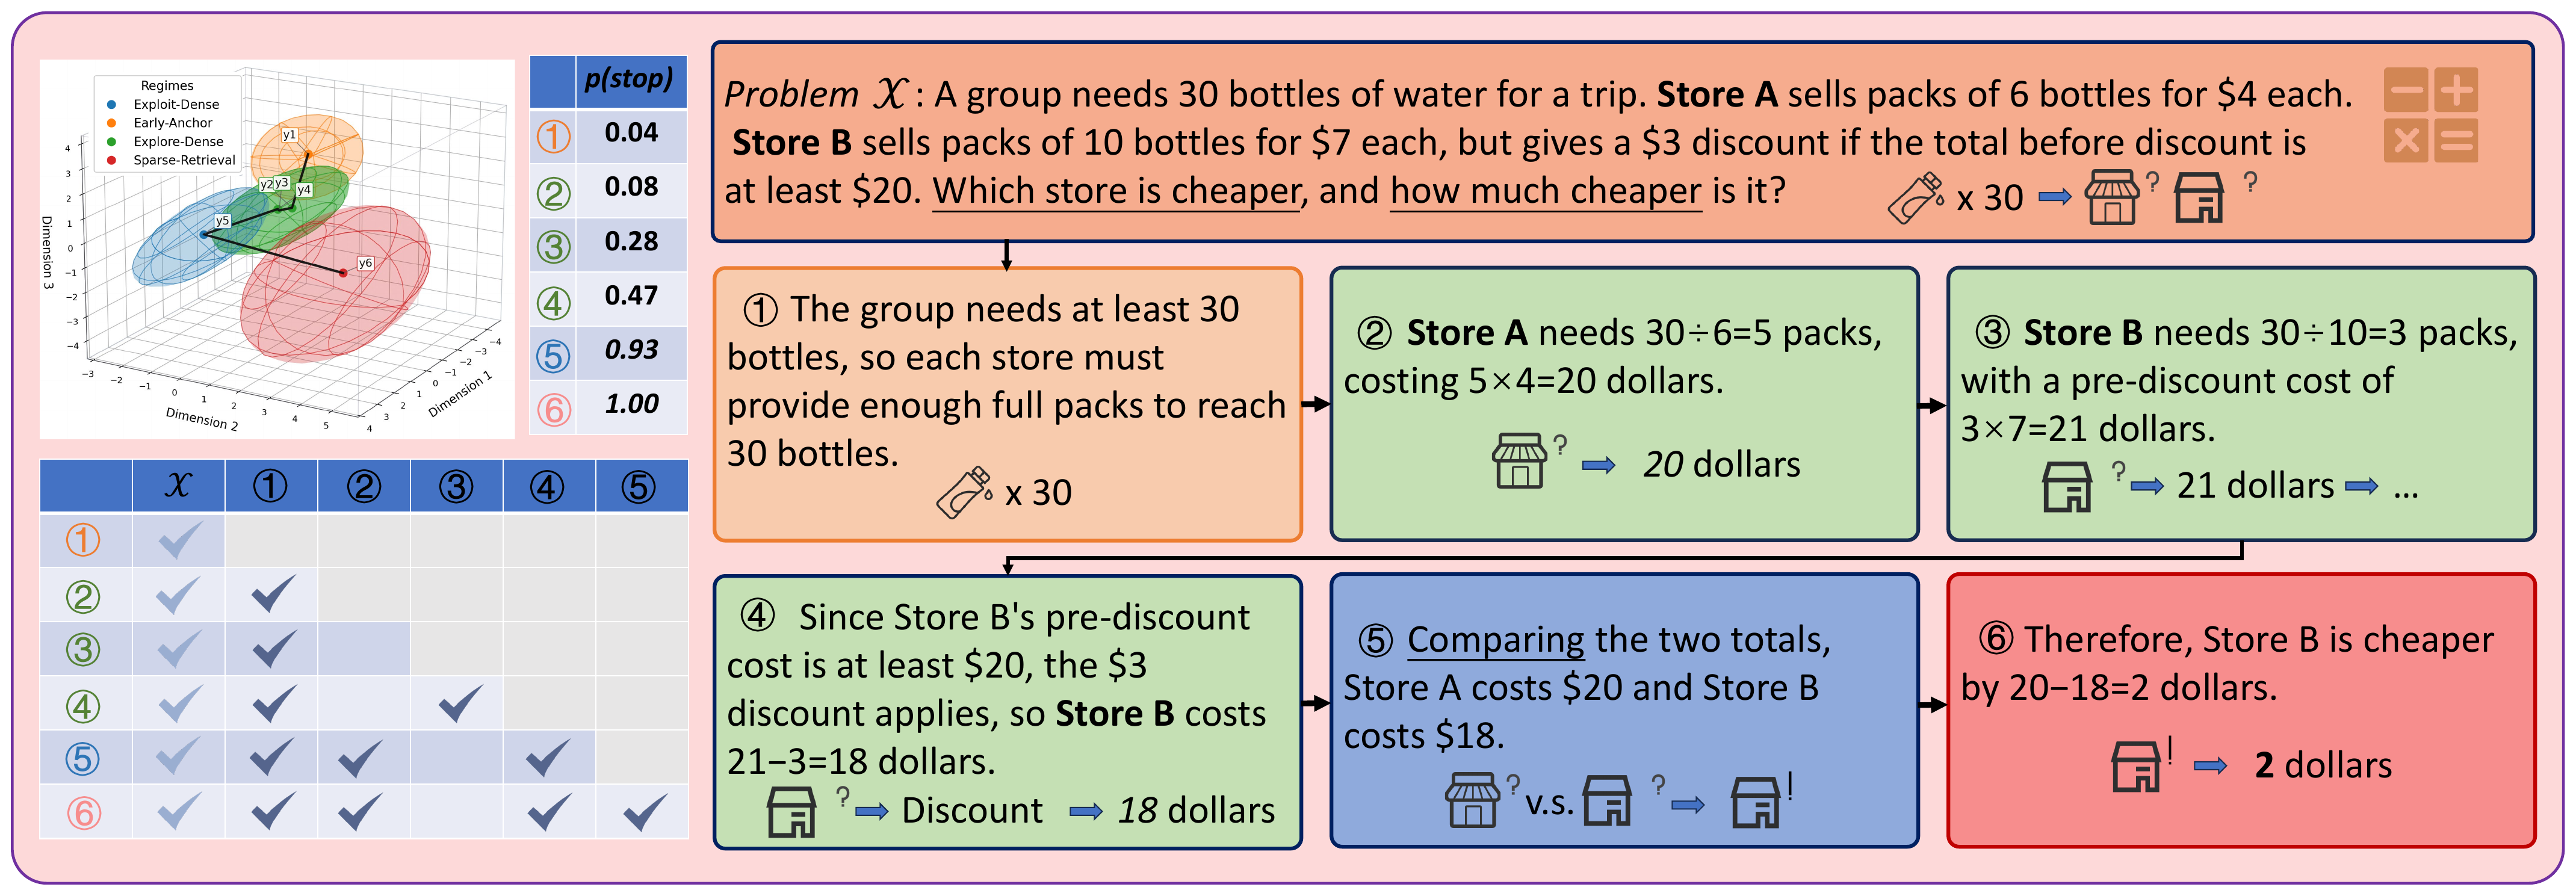
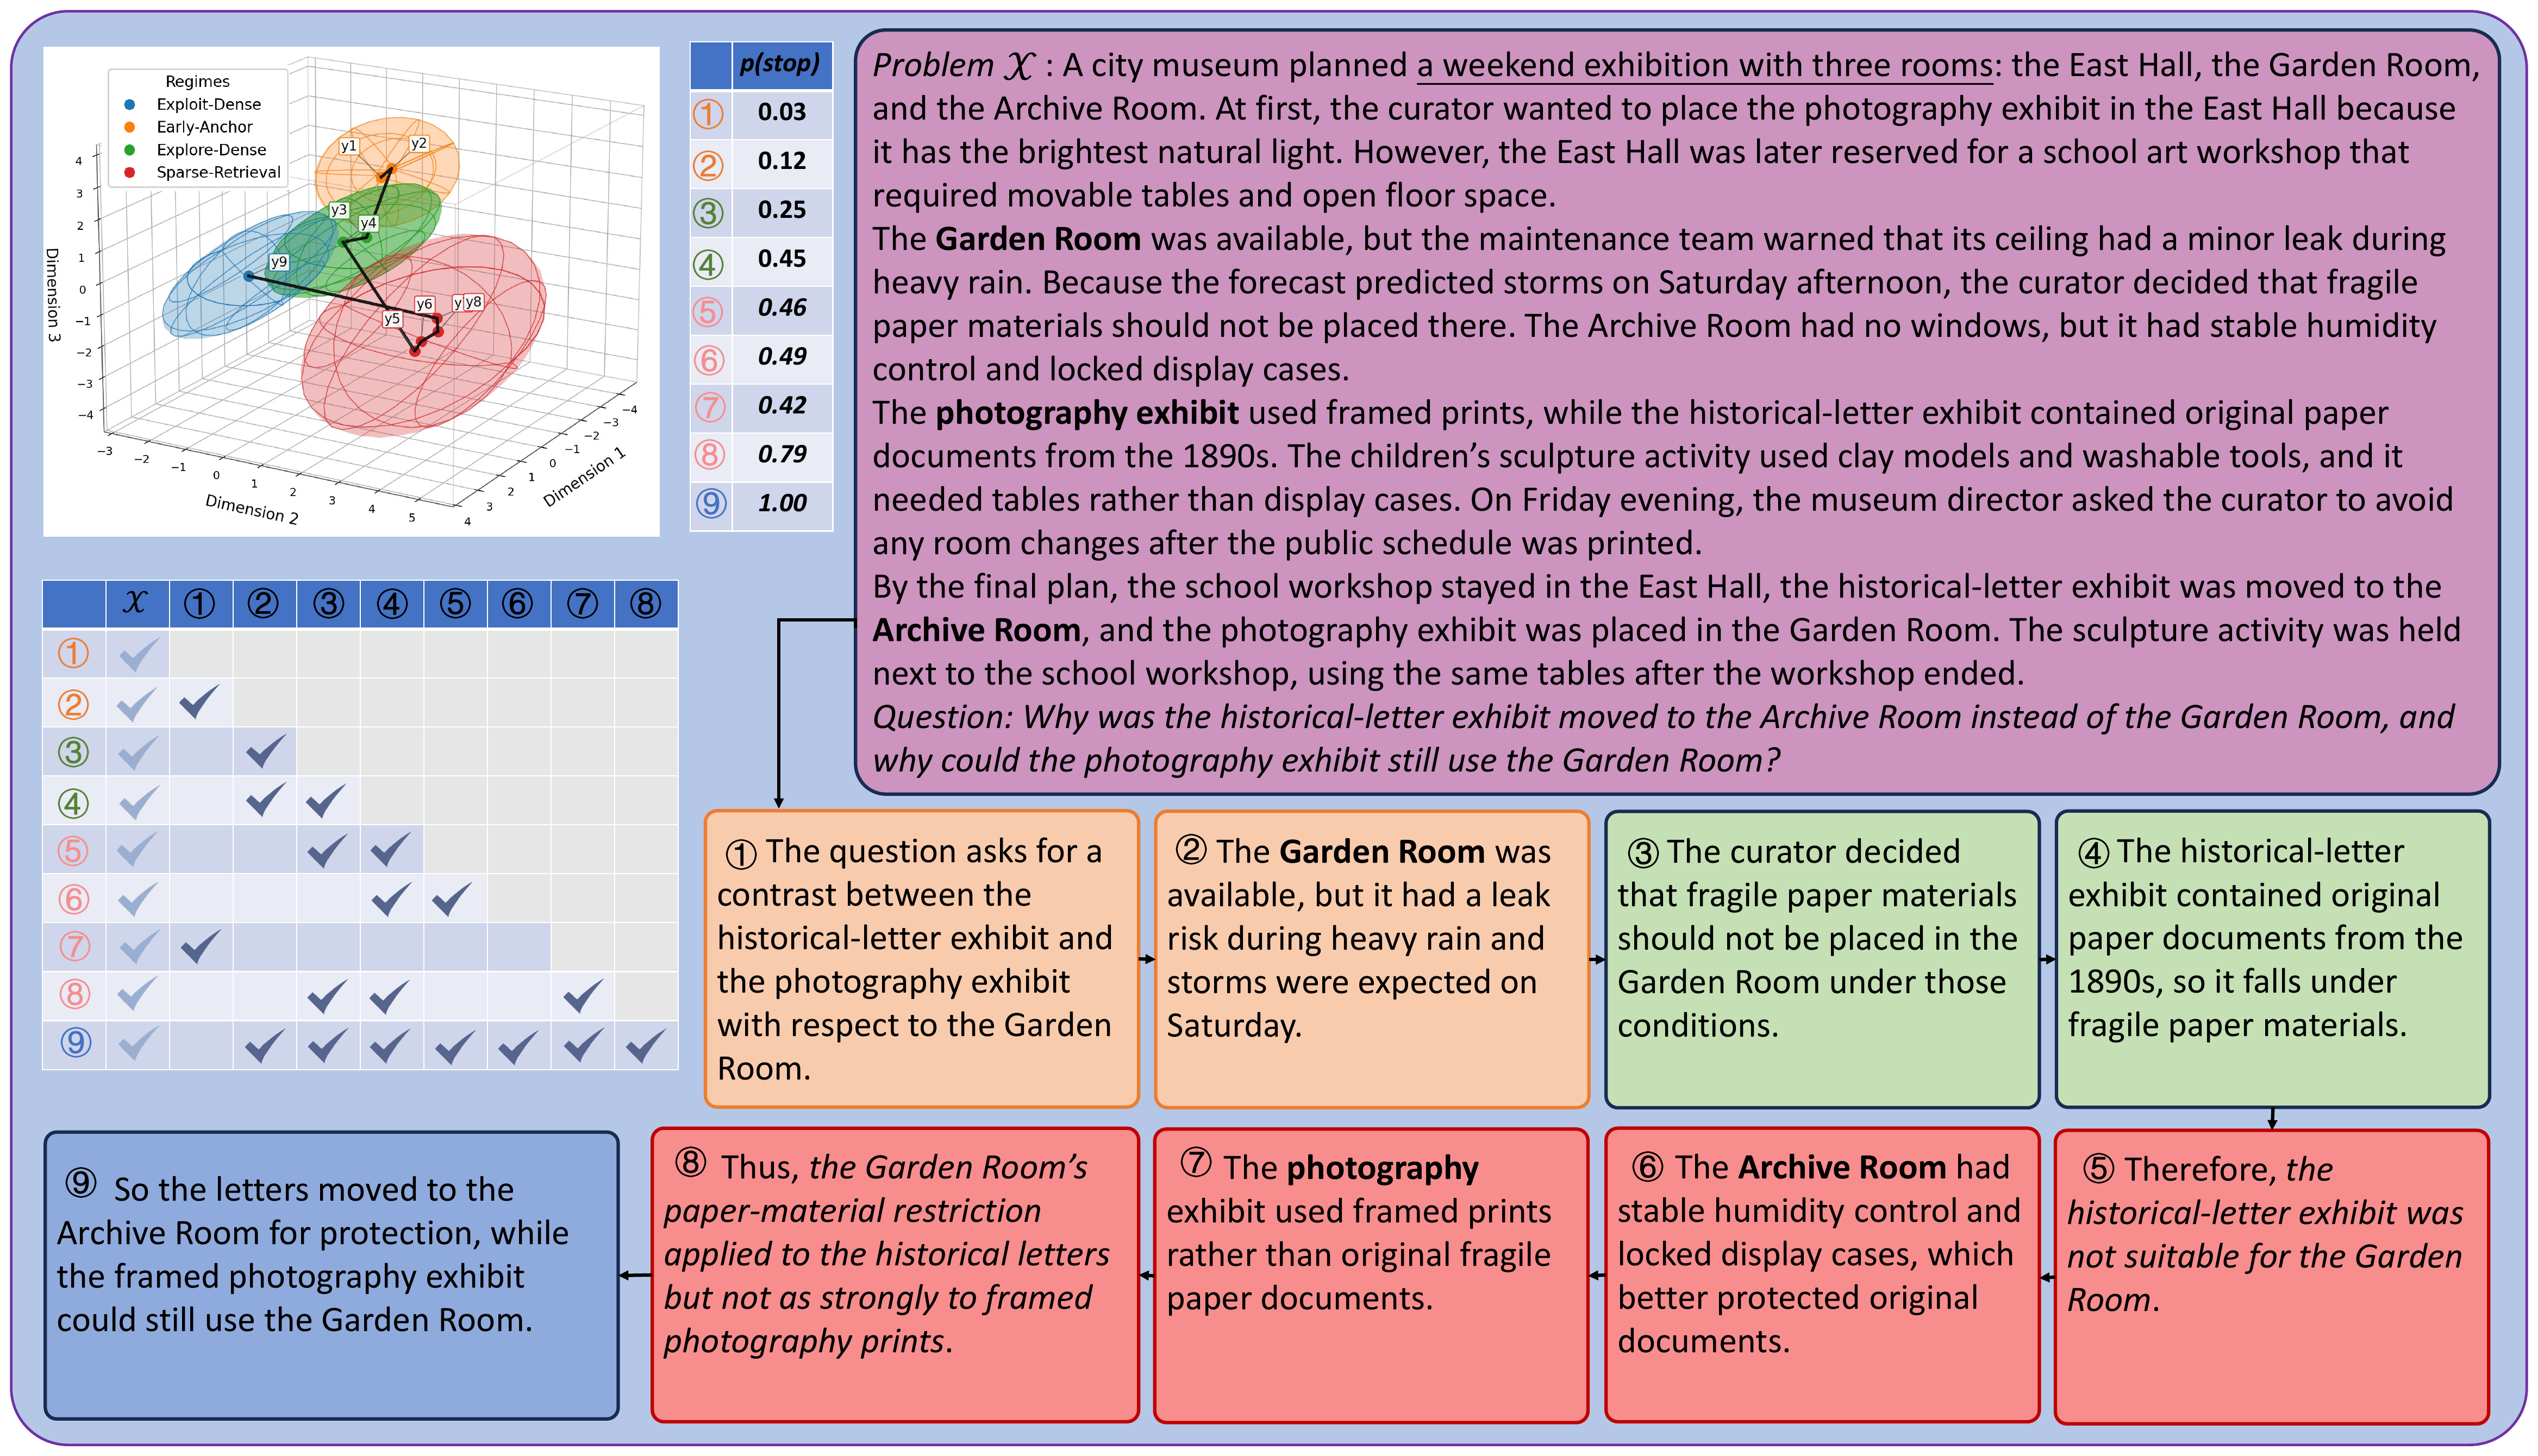
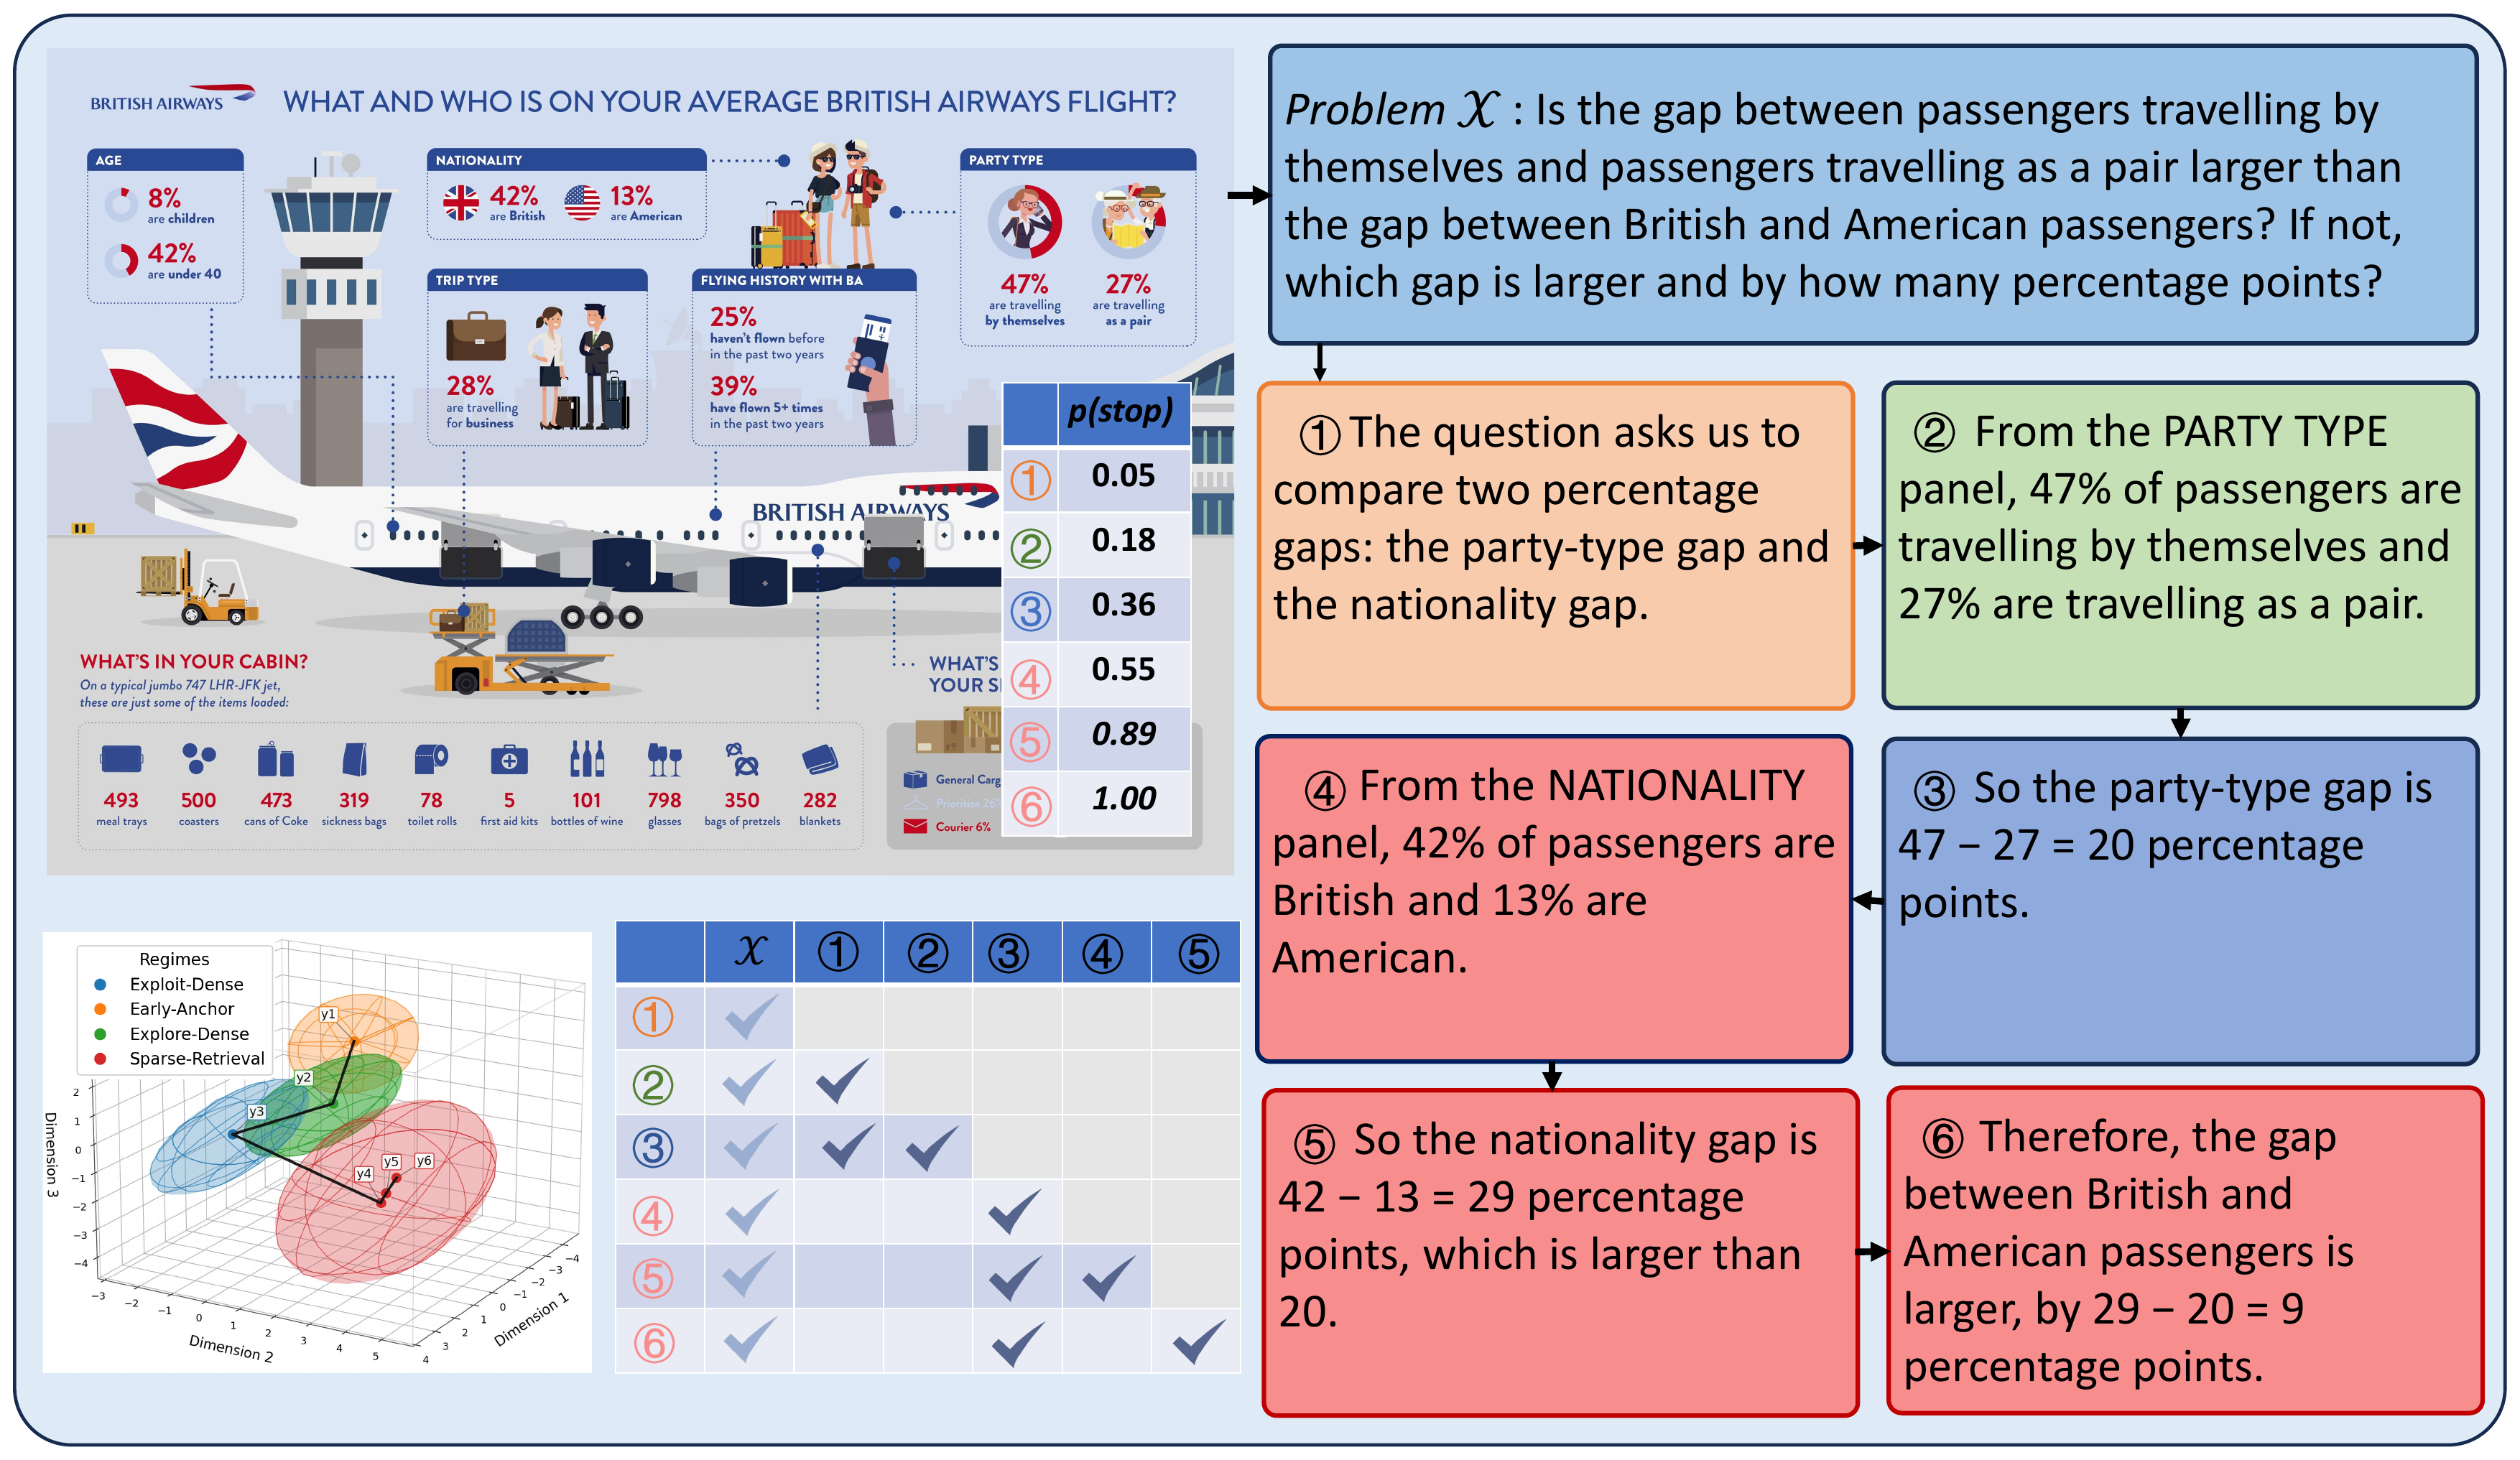
Test-time compute improves LLMs, but existing reasoning paradigms rely on externally imposed control — fixed
reasoning programs or costly search in constrained spaces — which limits both generalization and efficiency.
We propose State of Thought (SoT), a paradigm that enables endogenous reasoning,
with the model's own internal reasoning state governing how reasoning unfolds.
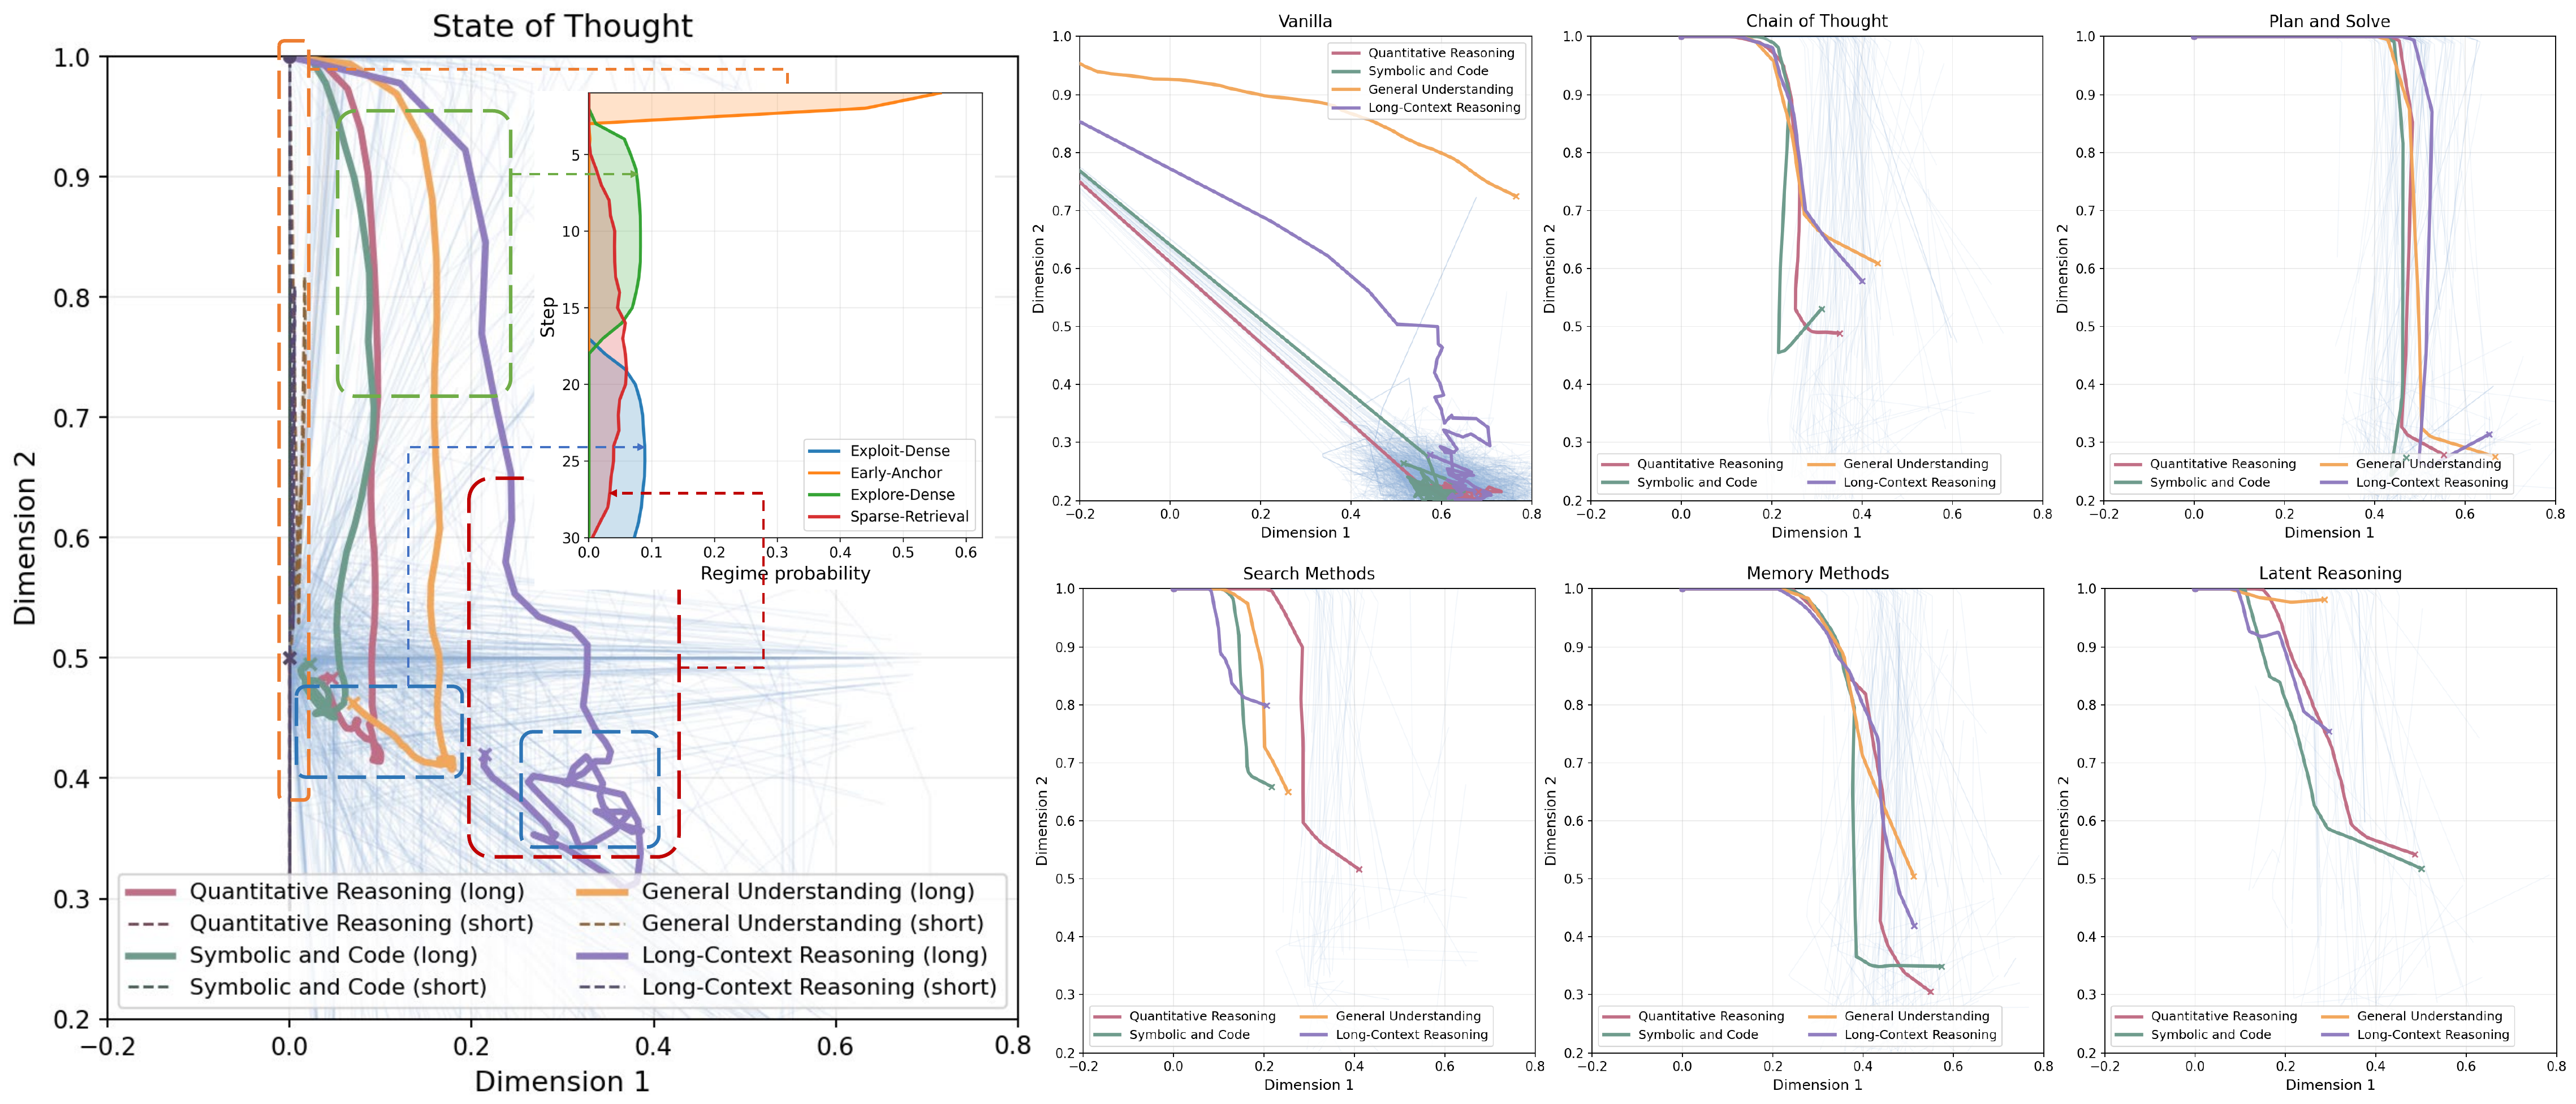
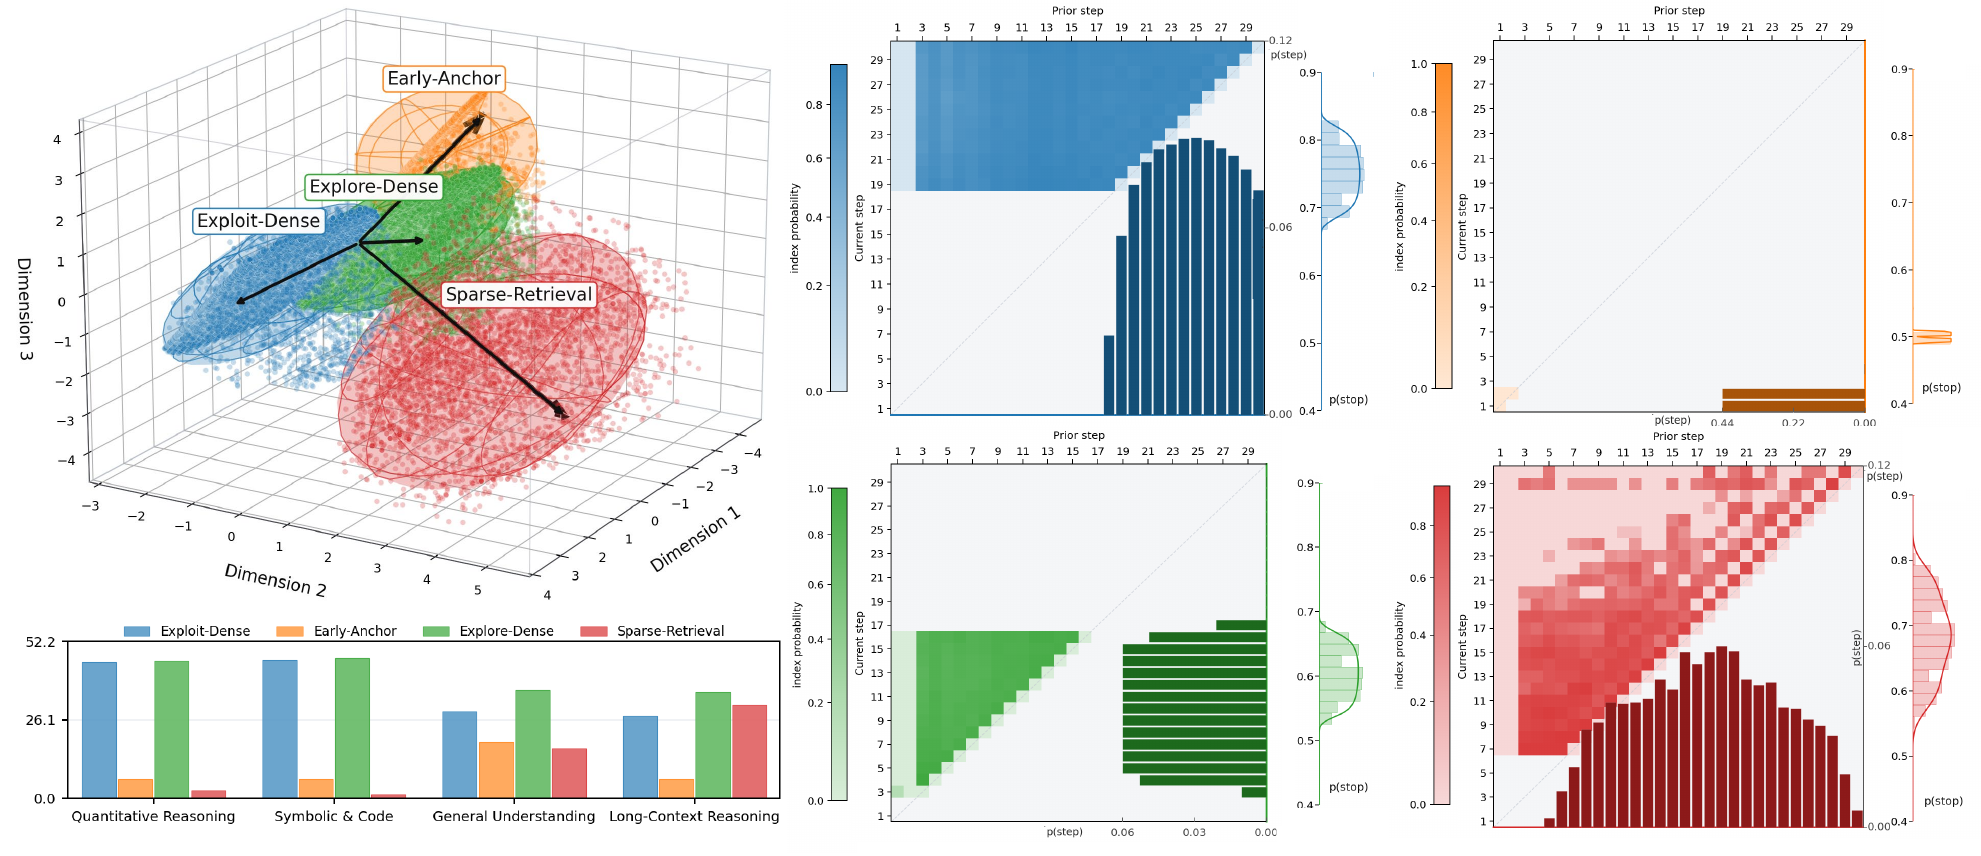
Concretely, SoT extracts a compact dynamics-geometric state from the model's internal information transfer
and uses a 582-parameter controller on frozen backbones to selectively activate the historical
reasoning support useful under the current state — framing reasoning as a state-conditioned process over
evidence rather than an externally prescribed token chain.
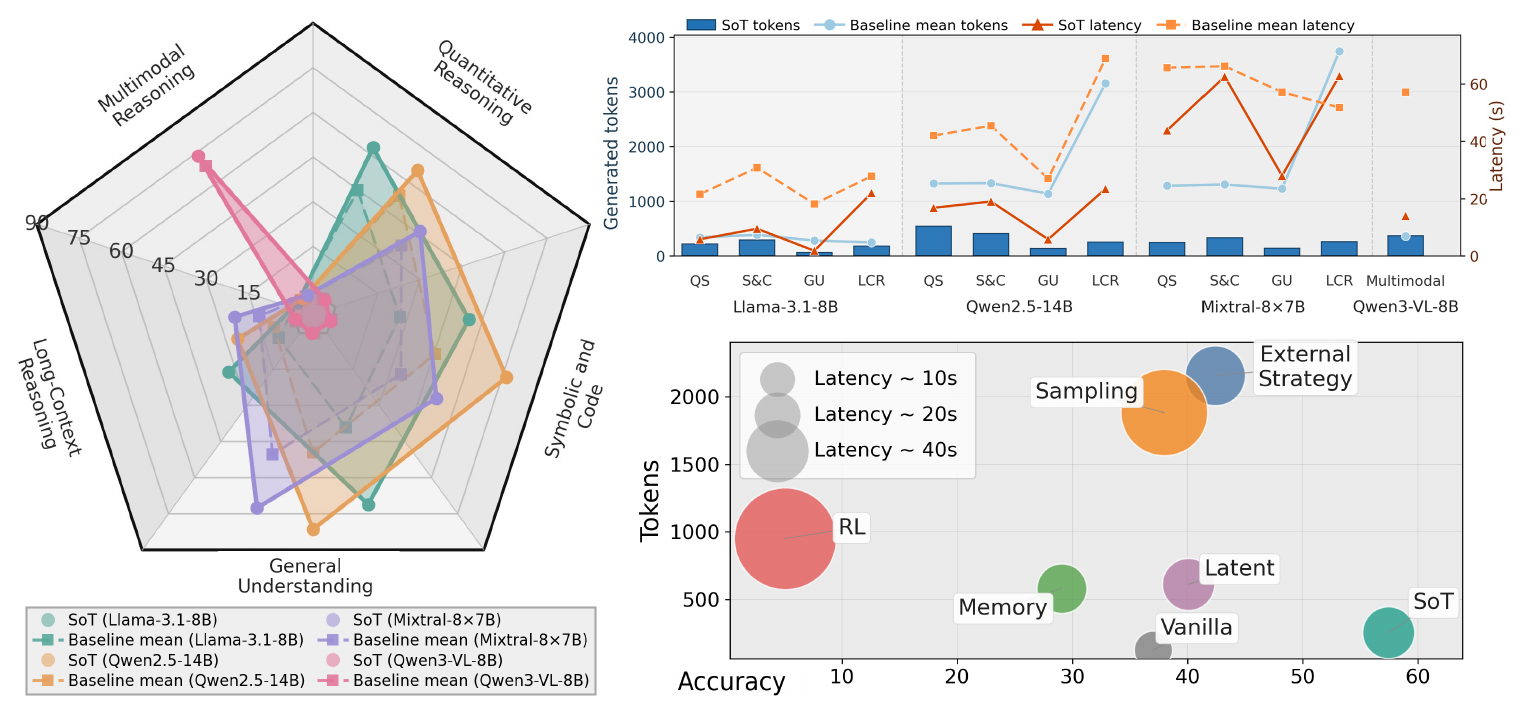
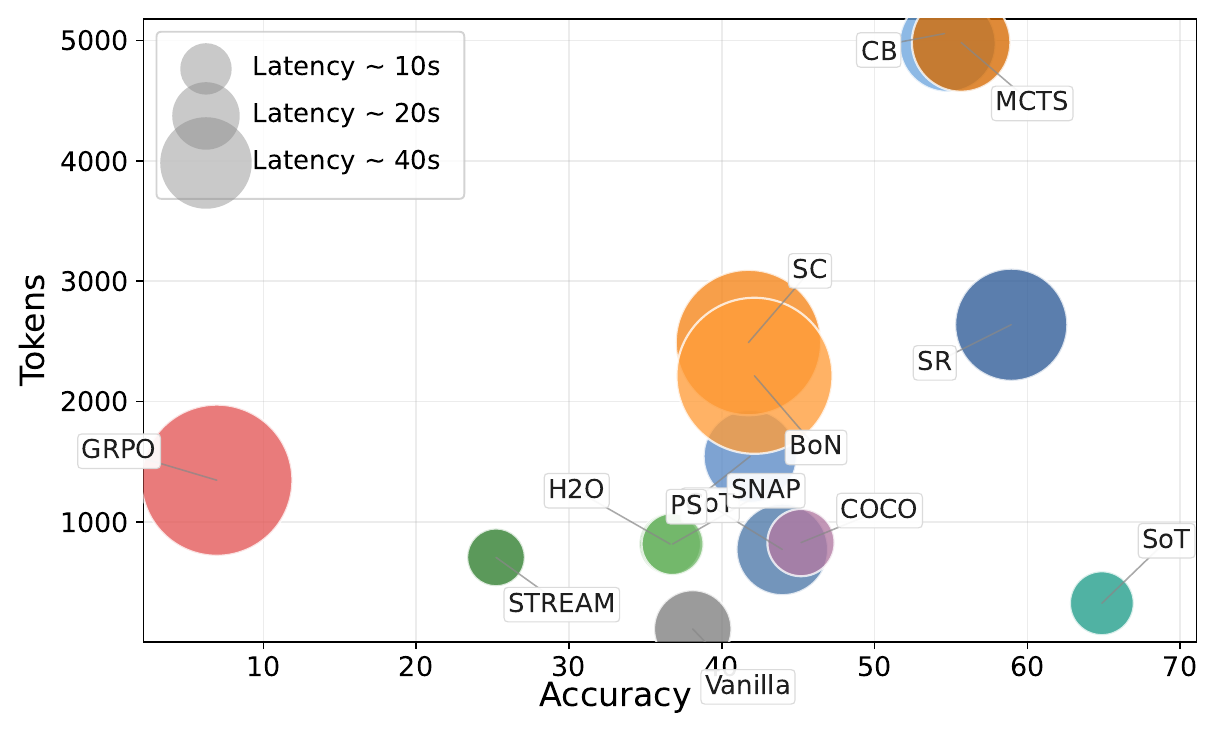
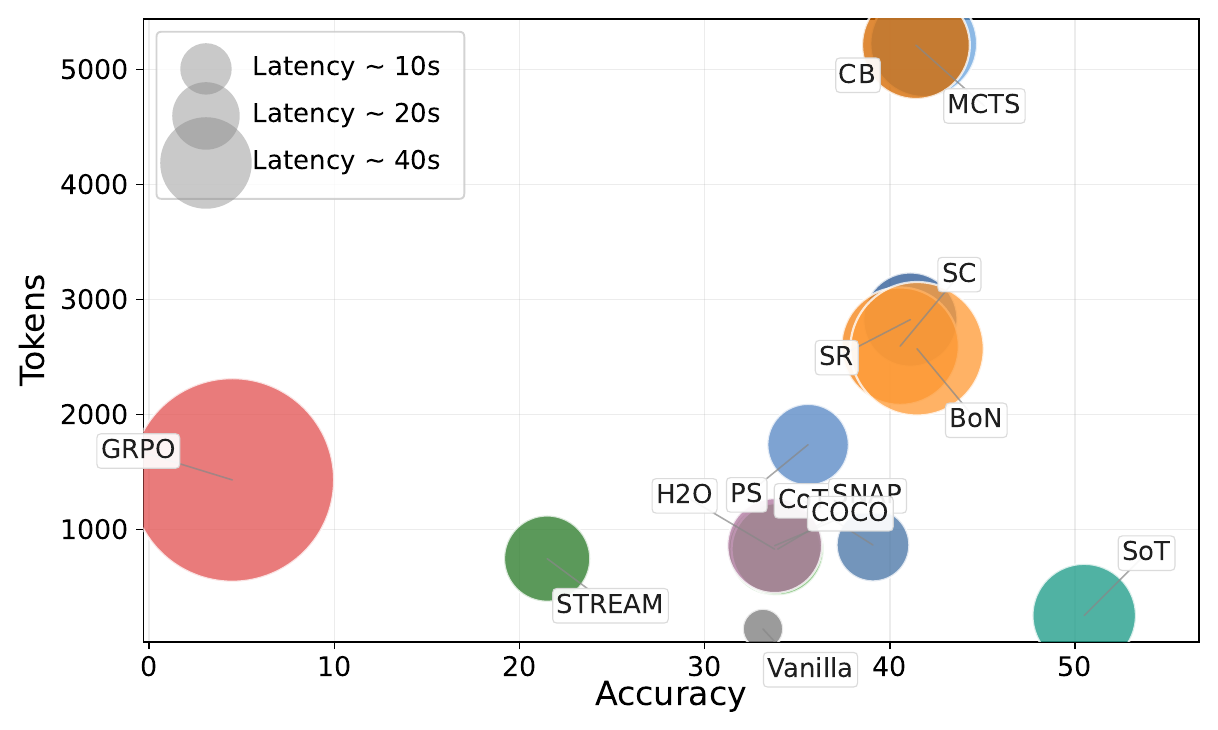
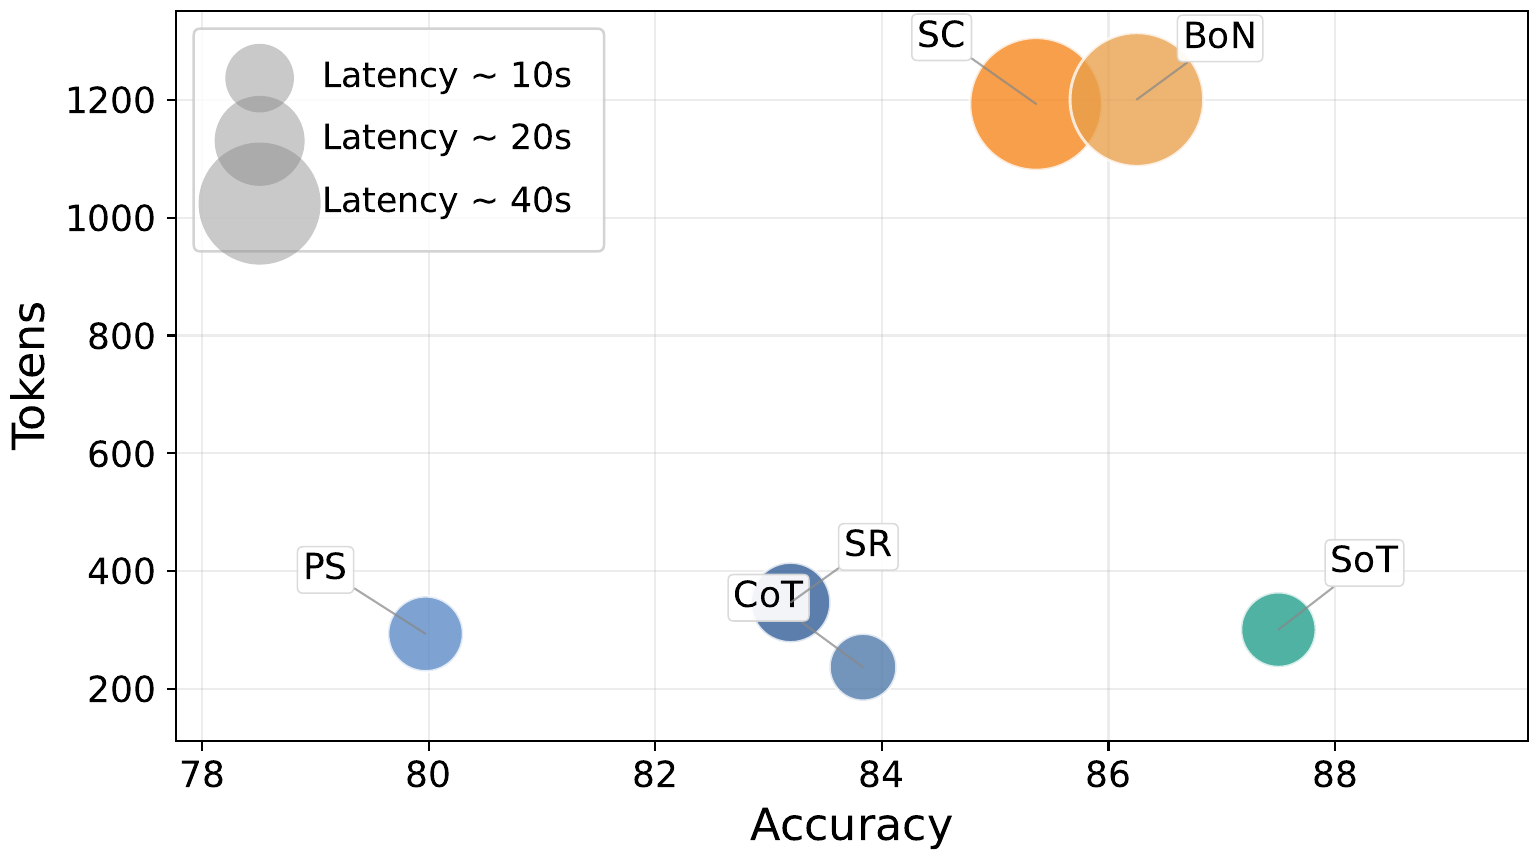
Across quantitative (1.34×), general (1.62×), symbolic-and-code
(1.76×), and long-context (2.51×) reasoning on 3 LLMs and 16 datasets,
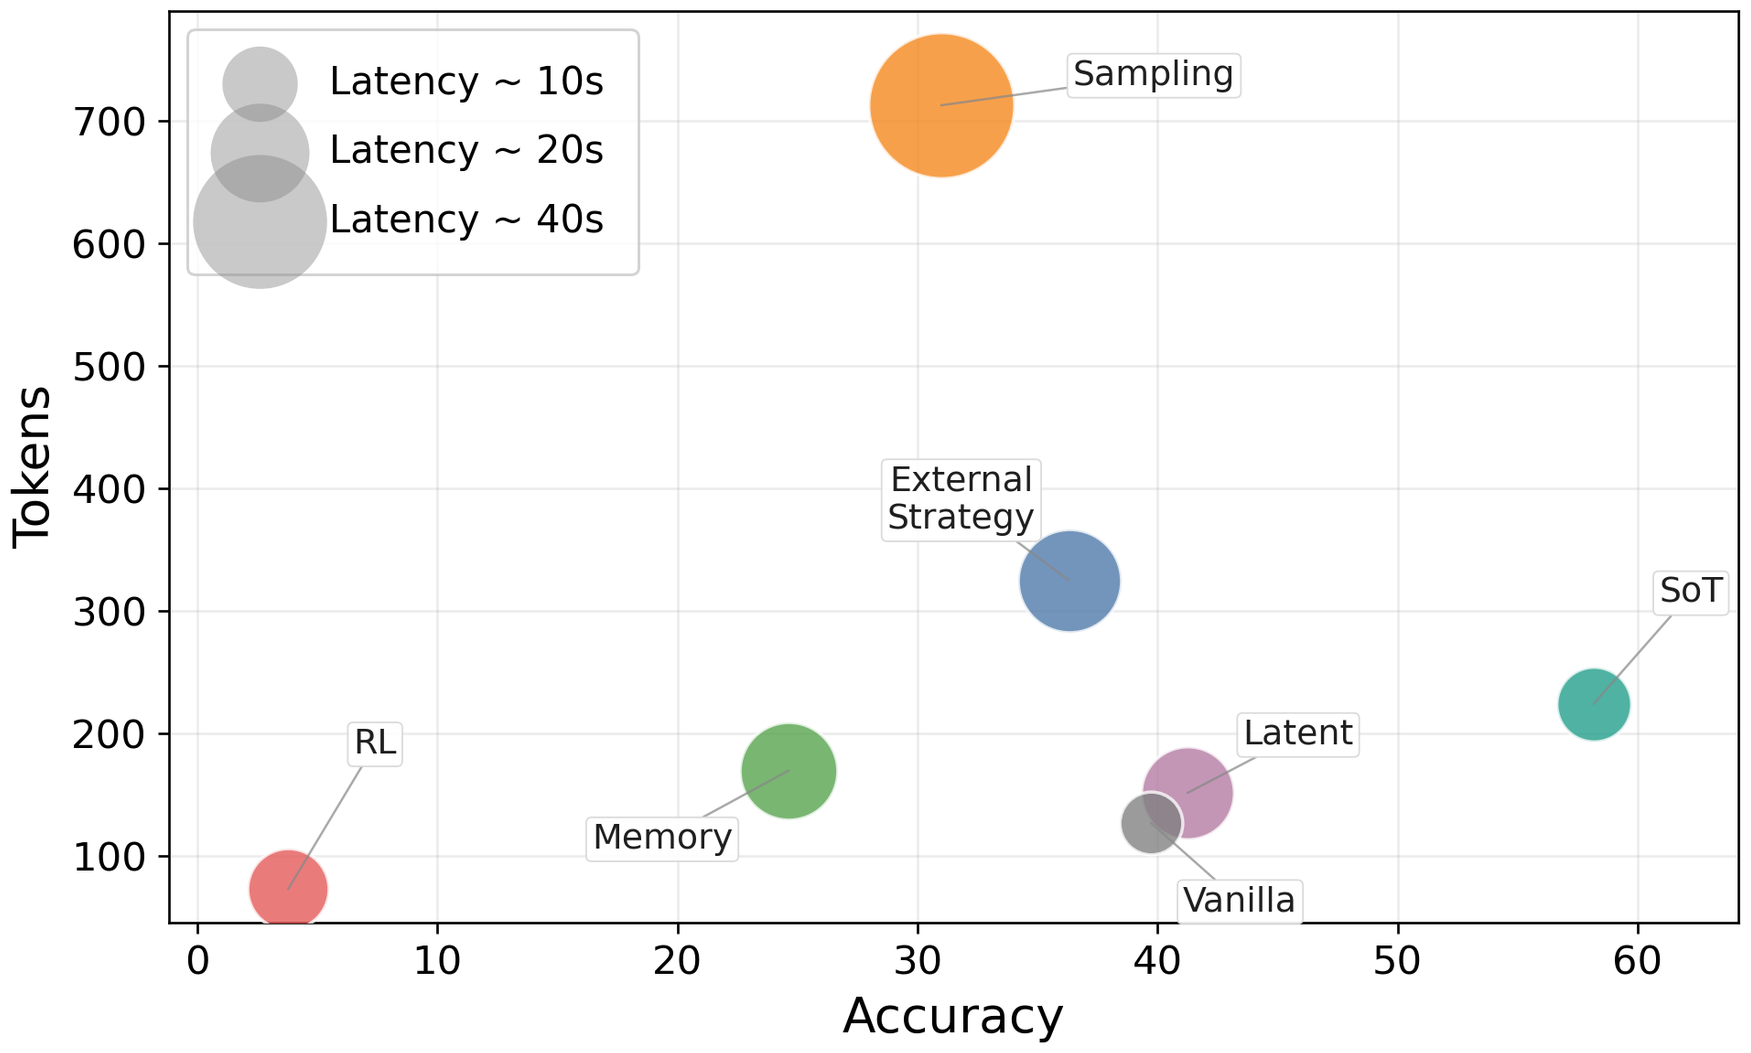
SoT consistently improves accuracy while reducing generated tokens by 62.6% and latency by
44.6%. Across 2 VLM scales and 3 tasks, it adds 3.8 points over reasoning
baselines with 74.9% fewer completion tokens and 73.5% lower latency than
search-based methods.