Preprint · Cross-Module Structured Pruning

CoCurve

Cross-Module Co-Pruning Curvature: a calibration-only method that prunes attention and FFN units jointly — by preserving the curvature of the edges between units, not just ranking the nodes.

Zhiren Gong1,2, Zihao Zeng1, Tiantong Wang1, Yixin Wang1, Honoka Anada1,4, Zijie Wang1, Ming Xiao5, Chau Yuen3, Wei Yang Bryan Lim1

1 College of Computing and Data Science, Nanyang Technological University 2 Interdisciplinary Graduate Programme, Nanyang Technological University 3 School of Electrical and Electronic Engineering, Nanyang Technological University 4 Department of Computer Science, The University of Tokyo 5 Information Science & Engineering, KTH Royal Institute of Technology

Across 6 LLMs (3B–70B) and 3 VLMs, CoCurve ranks first in 53/60 corpus comparisons (15/15 at 70B), and after the same lightweight recovery its structures stay strongest through 50% pruning. The catch everyone misses: the decisive curvature lives in the attention↔FFN edges, not the nodes.
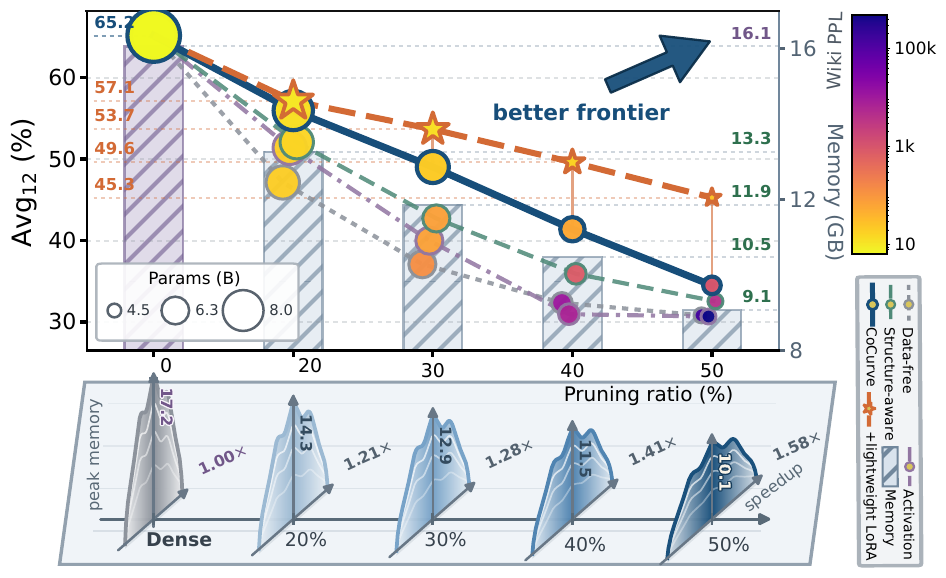
Quality–deployment frontier on Llama-3.1-8B-Instruct: Avg12 vs pruning ratio, with memory and prefill speedup
Figure. CoCurve advances the quality–deployment frontier on Llama-3.1-8B-Instruct — highest Avg₁₂ at every ratio, with prefill up to 1.58× and peak memory down to 0.59× dense.

6 LLMs · 3 VLMs

3B–70B, including a 70B 10–50% sweep

12 tasks + 7 MM

3 perplexity corpora · 12 language · 7 multimodal

53/60

Corpus comparisons ranked first (15/15 at 70B)

M ablations

Full edge matrix, no pairwise sweeps

1.58× · −41%

Prefill throughput / peak memory at 50%

Abstract

Structured pruning compresses LLMs by deleting whole units — attention heads and FFN channel groups. Almost every method scores each unit in isolation, implicitly assuming that the damage of pruning a set is additive. We show this is the wrong granularity for Transformers: because every sublayer reads from and writes to a shared residual stream, two individually weak units can be jointly indispensable, and two salient ones partly redundant.

CoCurve (Cross-Module Co-Pruning Curvature) casts structured pruning as set-dependent predictive risk over a unified inventory of attention heads and FFN groups. A second-order Taylor expansion of the token-level KL yields a single Fisher matrix: its diagonal is classical node saliency, while its off-diagonal entries are co-pruning curvature edges — the extra damage from removing two units together, conditioning each decision on the units already removed.

We prove this entire edge matrix is a Gram product of single-unit ablations, recovering it from just M ablations with no pairwise sweeps, gradients, or labels — then prune in one shot under a shared budget. Across 6 LLMs (3B–70B) and 3 VLMs, over 3 perplexity corpora, 12 language tasks and 7 multimodal benchmarks, CoCurve ranks first in 53/60 corpus comparisons and moves the quality–deployment frontier.

The Problem · Nodes Aren't Independent

Isolated scoring is the wrong granularity

The standard recipe gives every unit an importance score and assumes set damage is additive: ΔL(S) ≈ Σ ΔL(u). But a Transformer is a coupled system — every sublayer reads and writes one shared residual stream, so pruning effects reinforce or cancel. Pruning a set is a joint operation, not a sum.

Bridge units get co-pruned

The consequence: a node-first ranker inevitably co-prunes a low-saliency bridge unit (87 of 768 on Llama-3.1-8B; 3.5–14.5% across ten models) together with the units that depend on it. Two weak-looking units can be jointly indispensable; two salient ones partly redundant. Modeling the interactions is what unlocks further progress along the frontier.

Method

CoCurve · live Score units alone and you miss bridge units — cheap on their own, load-bearing together. CoCurve reads that coupling off one matrix.
The problem — damage isn’t additive
a Transformer shares one residual stream, so units interact
shared residual stream
attn A
FFN B
remove A0.0
remove B0.0
predicted A+B0.0
actual A&B0.0
The gap (+1.2) is co-pruning curvature — invisible to any score that rates units one by one.
The fix — one matrix, two readings
diagonal = node saliency · off-diagonal = cross-module edges
H = F·Fᵀ  — every edge from just M single-unit probes
M probes
single-unit ablations build the whole N×N matrix, no pairwise sweep
every class
leads all capability classes on Llama-3.1-8B at 20% sparsity
training·free
no gradients, no labels, no retraining of the backbone

The bridge gap on the left is exactly an off-diagonal entry on the right. CoCurve recovers the whole edge matrix as a Gram product of M single-unit ablations — no pairwise sweeps, gradients, or labels — then prunes attention & FFN jointly, never deleting a bridge with what it holds up.
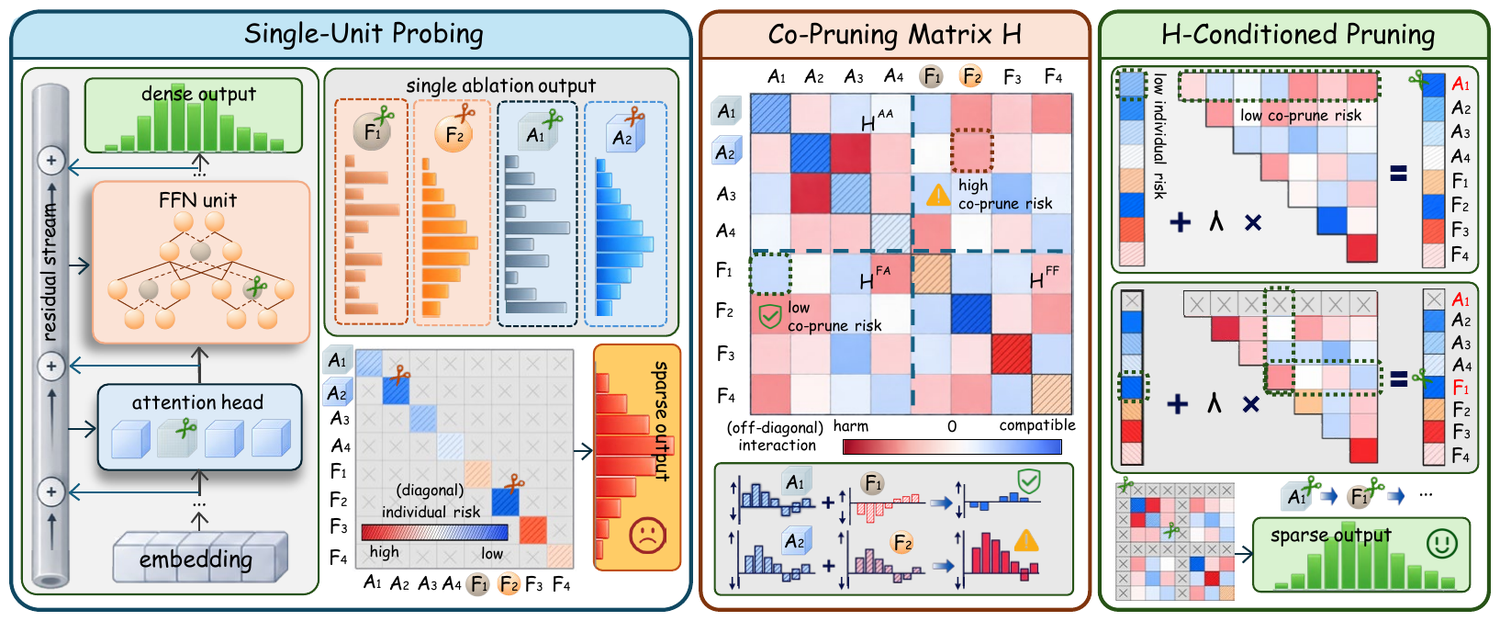
CoCurve overview: single-unit probing, co-pruning matrix H, H-conditioned pruning
Figure. CoCurve, end to end — probe each unit once (single-unit responses), assemble the co-pruning matrix H (diagonal saliency + off-diagonal edges), then prune conditioned on H.

One Fisher matrix, read two ways

Because the masked student equals the teacher at zero pruning, both the risk and its gradient vanish there, so the leading term of the token-level KL is purely second order: R(s) ≈ ½·sᵀH·s. The single matrix H carries everything.

Diagonal = node saliency

  • H_uu is exactly classical single-unit importance — a structured Optimal Brain Damage.
  • Non-negative by construction: a built-in correctness check on the estimate.
  • Yet on real models the diagonal alone misses the decisive coupling.

Off-diagonal = co-pruning edges

  • H_uv = the extra damage from removing u and v together.
  • Positive → jointly harmful; negative → perturbations cancel; zero → independent.
  • These attention↔FFN cross-module edges carry the decisive mass.

Recovered from M ablations — the Gram theorem

  • In the Fisher metric, H = (1/P)·D̄ᵀD̄ is a Gram product of single-unit ablation features.
  • So the full M×M edge matrix comes from M single-unit ablations — no O(M²) pairwise sweeps, no gradients, no labels.
  • A one-shot O(MK) cost-normalized greedy solves a shared attention+FFN budget, so per-type ratios emerge from the objective.
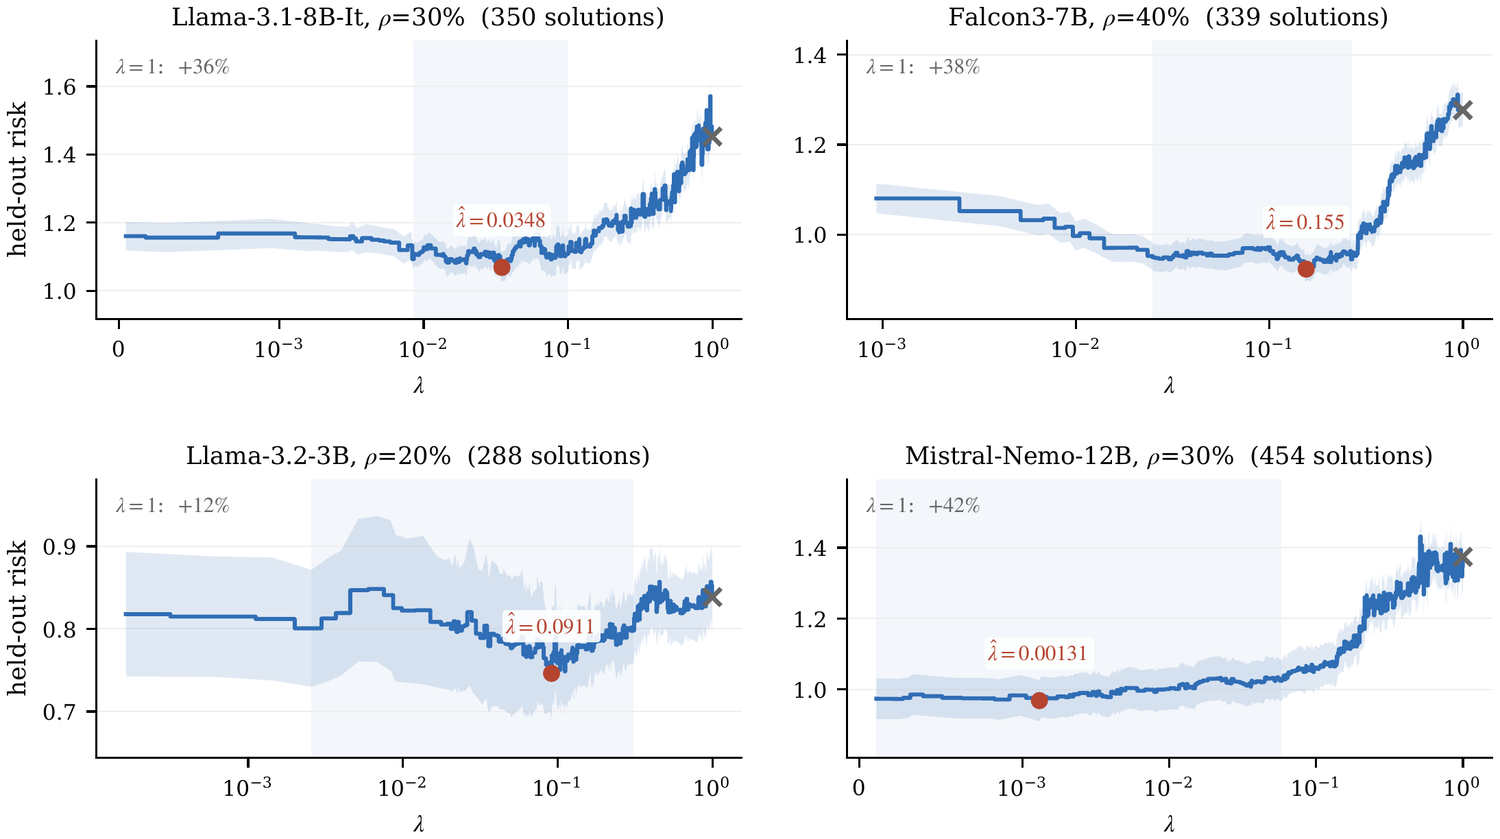
  • A calibration-selected λ ∈ [0,1] traces a positive-semidefinite path from diagonal-only (λ=0, an OBD floor) to the full co-pruning graph (λ=1); λ indexes candidate masks, and every intermediate matrix stays PSD.

Step 1 · Ablate

Run M single-unit ablations on a small calibration set; extract Fisher-weighted delta-logit features.

Output: the features whose Gram matrix is H.

Step 2 · Assemble H

Form the single Fisher matrix — diagonal saliency and off-diagonal co-pruning edges — with no pairwise sweep.

Output: node saliency + attention↔FFN edges together.

Step 3 · Prune once

Cost-normalized greedy under a shared budget, λ selected from calibration risk; physically remove units.

Result: a jointly-pruned subnetwork — slicing is bit-identical to masking.
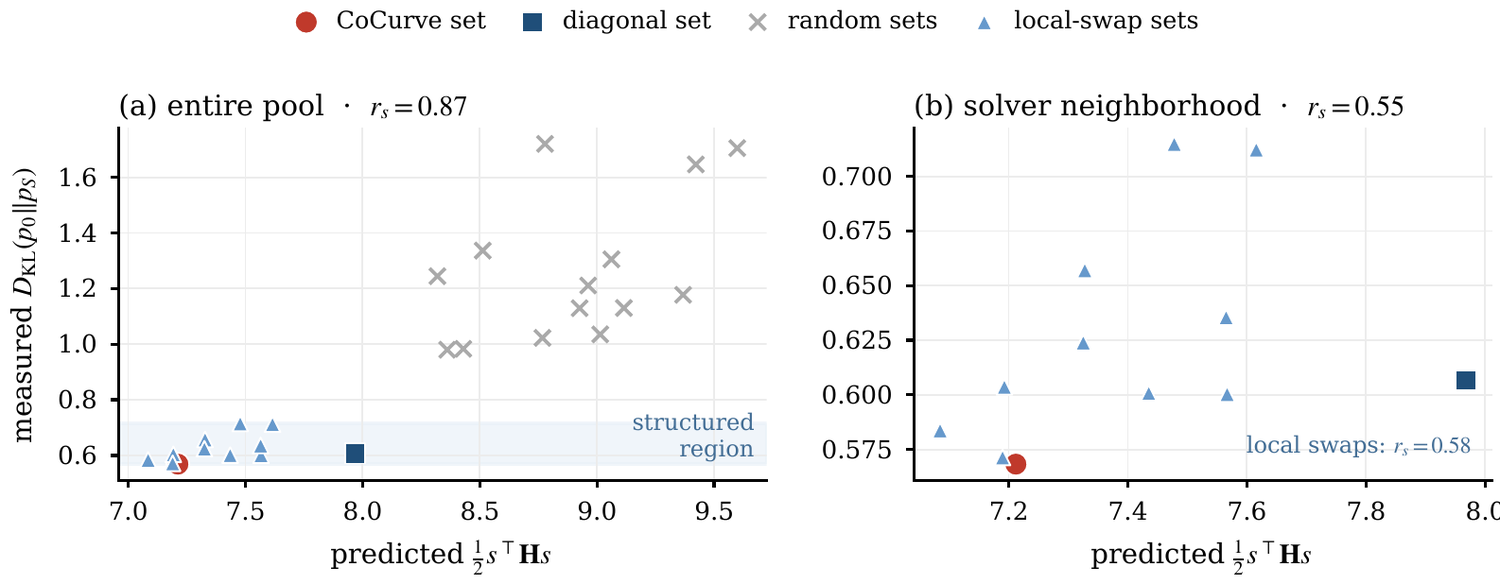
Predicted vs measured set risk, entire pool and solver neighborhood
Figure. The single-unit Gram surrogate predicts true set risk: across the candidate pool the predicted ½sᵀHs tracks measured KL at Spearman 0.87, and stays informative inside the solver neighborhood.
Held-out calibration risk along the lambda path for four models
Figure. Held-out calibration risk along the PSD path λ∈[0,1] — a clear interior minimum selects λ per model, without labels.

Main Results

Llama-3.1-8B · 20%

56.0 Avg₁₂ vs 54.5 best baseline (dense 65.2) · Wiki 12.9

Leads all 8 Avg₁₂ blocks on the 8B/24B models from 20–50%.

First in 53/60 corpora

Across 6 LLMs (3B–70B) — 15/15 at 70B

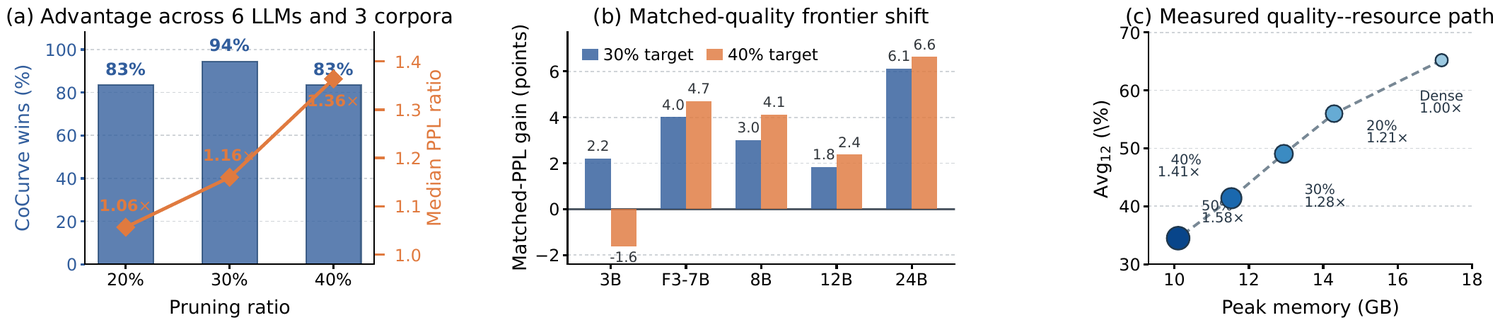
Matched-quality interpolation permits 2.2–6.6 more pruning points in 9/10 cases.

Mechanism, not luck

Bridge removal degrades 19/20 capability groups by up to 23.7 points

Organized within- and cross-module edges reverse real pruning decisions across 10 LLMs and 7 VLMs.

Main Table — 20% Structured Pruning (WikiText ↓ · task-group accuracy % ↑ · Avg₁₂ ↑)

Hint: scroll horizontally to view all columns on smaller screens. Cmn₄ = commonsense (4 tasks), Sci₃ = science QA (3), Read₄ = reading (4), MMLU = knowledge (1). Best baseline = LLM-Pruner.

ModelMethodWiki ↓Cmn₄ ↑Sci₃ ↑Read₄ ↑MMLU ↑Avg₁₂ ↑
Llama-3.1-8B-InstructDense6.470.960.167.647.865.2
Best baseline13.262.244.858.536.854.5
CoCurve12.963.748.058.638.556.0
Mistral-Small-24BDense4.773.563.465.952.366.7
Best baseline25.865.555.259.843.759.2
CoCurve9.067.856.360.943.560.6
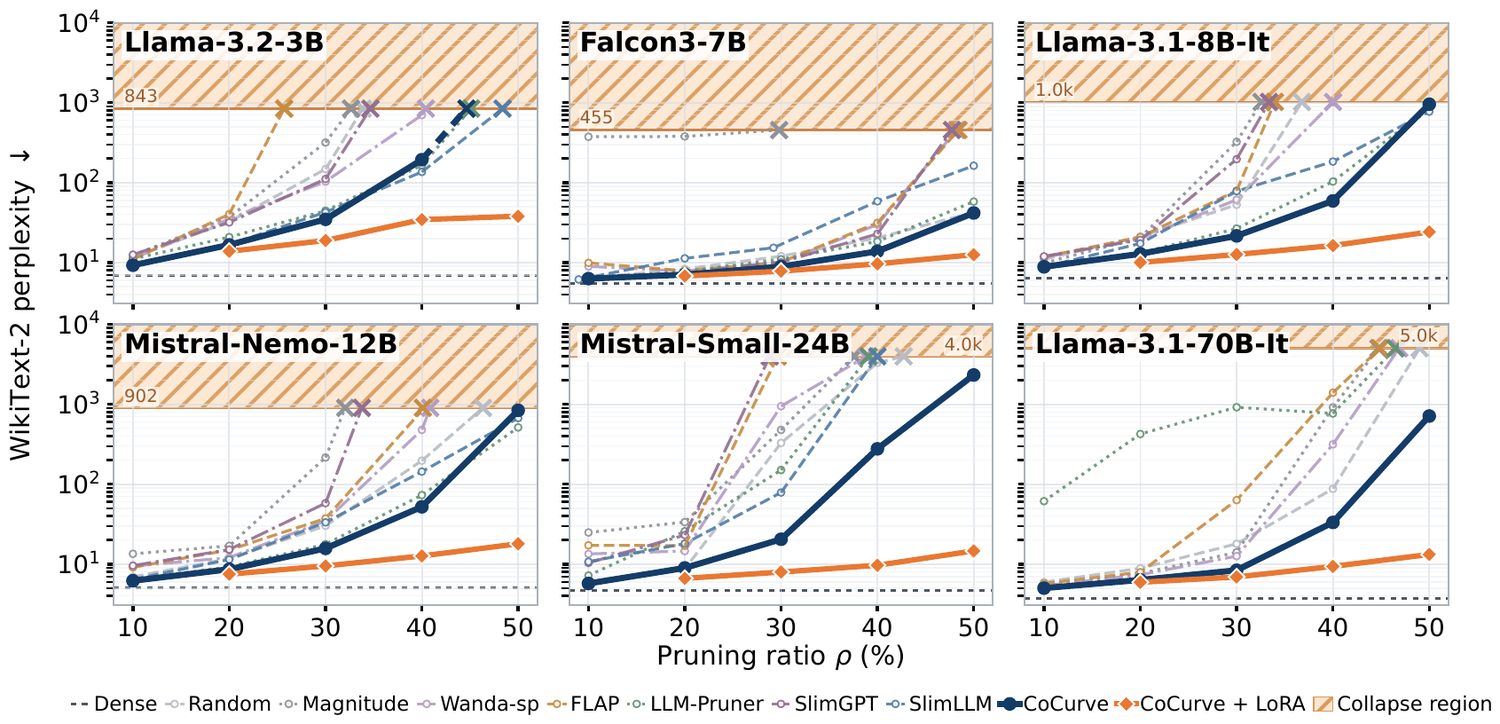
WikiText-2 perplexity across pruning ratios on six LLMs
Figure. WikiText-2 perplexity across pruning ratios on six LLMs (3B–70B) — CoCurve (blue) stays lowest through the moderate regime; selection-only baselines enter the shaded collapse zone.
Advantage across models and corpora, matched-quality frontier shift, quality-resource path
Figure. (a) CoCurve's advantage across 6 LLMs and 3 corpora; (b) the matched-quality frontier shift (2.2–6.6 more pruning points); (c) the measured quality–resource path.

Recovery · The Lead Survives Fine-Tuning

Better structures recover better

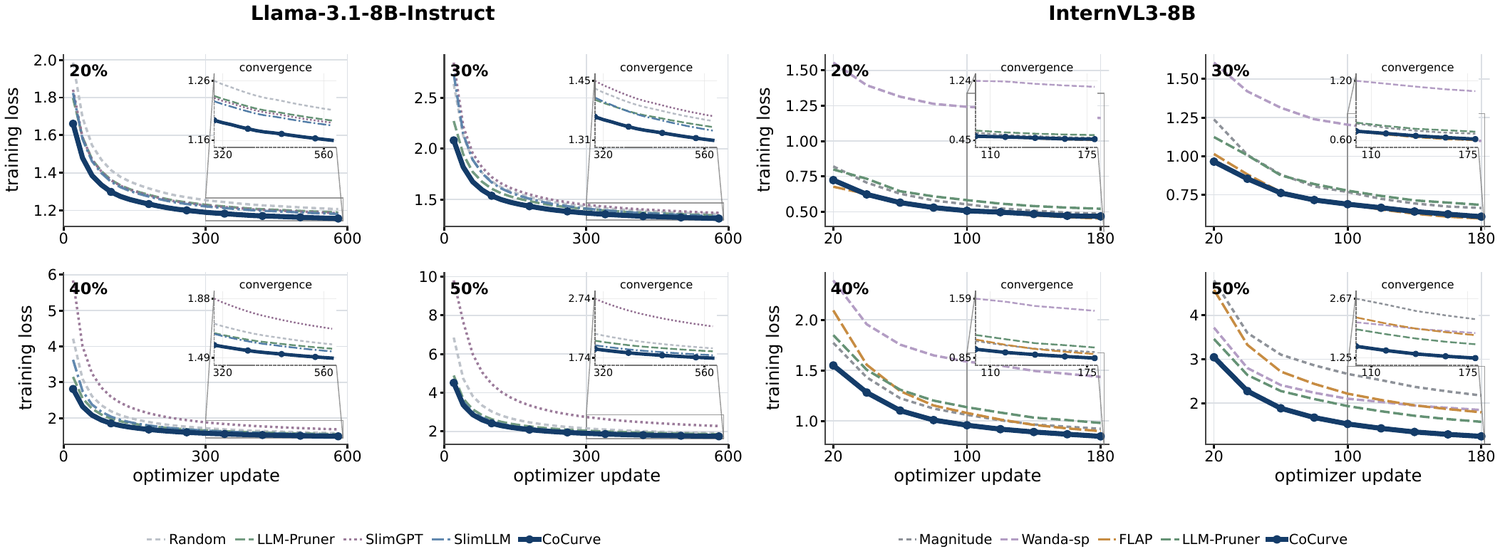
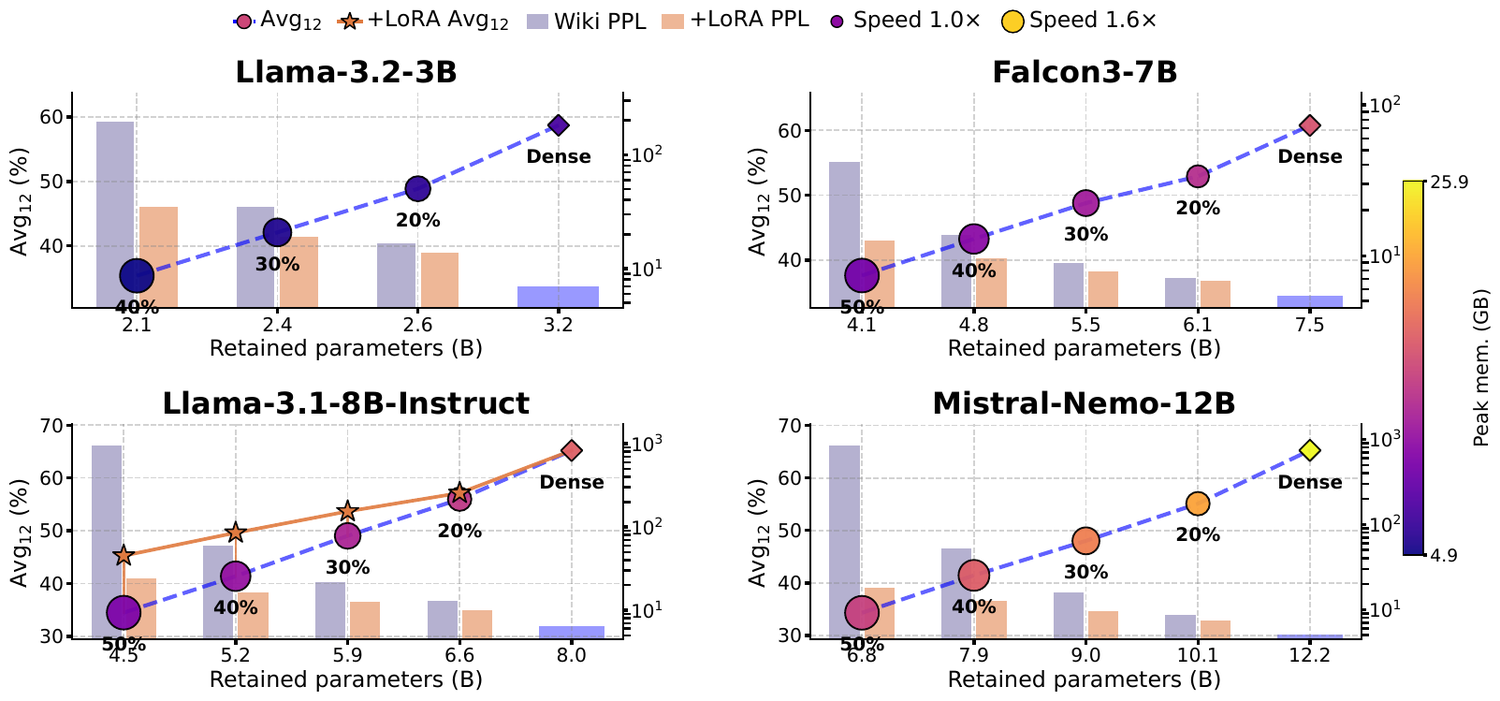
Selection is calibration-only, but the pruned checkpoint can be refined with the same lightweight LoRA recovery given to every method. CoCurve's retained structures remain strongest all the way through 50% pruning: on Llama-3.1-8B the recovery raises Avg₁₂ by 10.8 points and cuts selection-only perplexity from 41.7–4616.9 down to 12.6–38.0.

Because CoCurve starts from a healthier subnetwork, recovery converges to a higher plateau — the head start compounds rather than washing out.
Recovery trajectories across models and ratios
Figure. Recovery trajectories under the common LoRA recipe — CoCurve-pruned checkpoints optimize to the highest quality across models and pruning ratios.
Quality-efficiency after recovery across four LLMs
Figure. Quality–efficiency after recovery — Avg₁₂ and WikiText perplexity against retained parameters, annotated with realized speedup, across four LLMs.

Vision–Language Models

The same edges transfer to VLMs

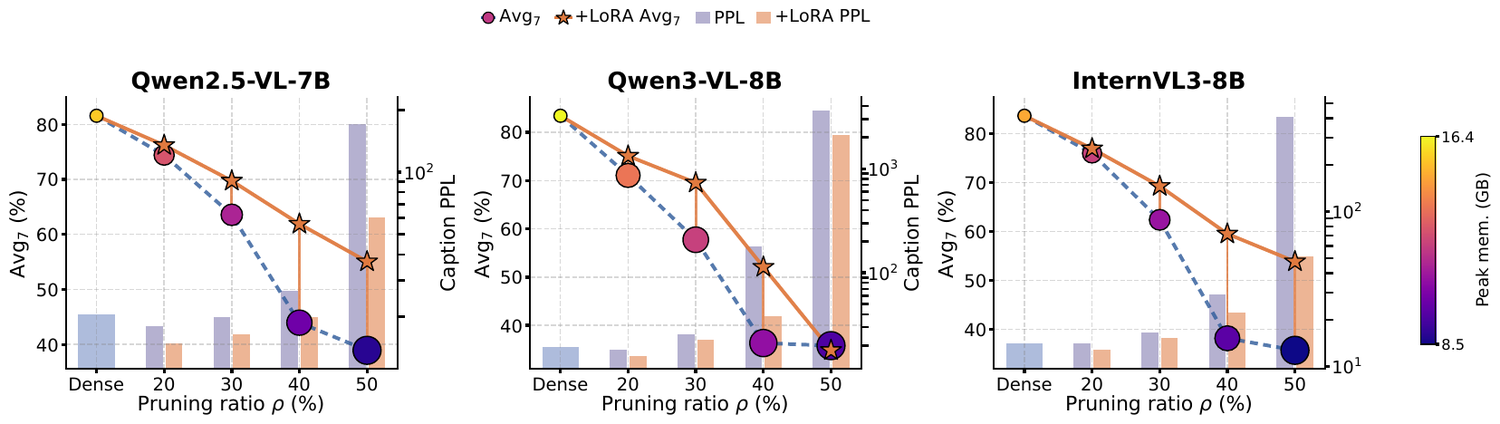
CoCurve applies unchanged to the language tower of vision–language models. Across three VLMs it leads every Avg₇ block along the pruning sweep, and at 30% improves over the strongest external pruner by 4.9, 10.7, and 1.1 points respectively.

The cross-module coupling is not a language-only artifact — the mechanism analysis spans 7 VLMs and finds the same organized edge structure.
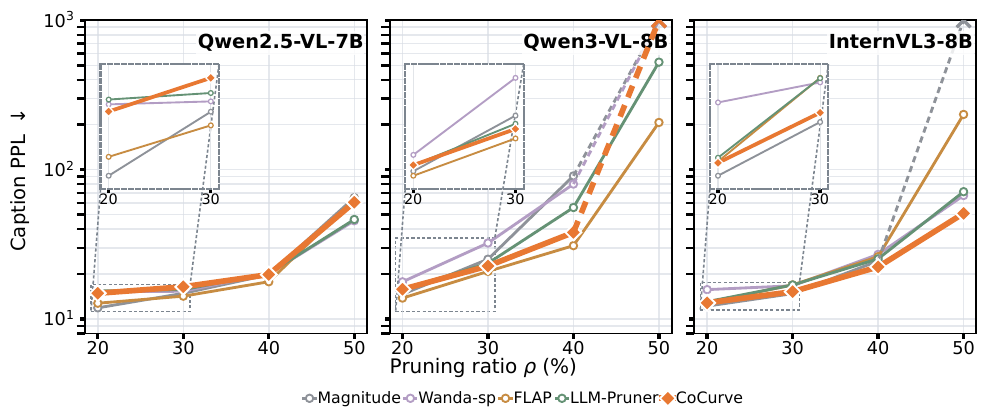
Caption perplexity across pruning ratios on three VLMs
Figure. Caption perplexity across pruning ratios on three VLMs — CoCurve stays lowest as sparsity grows.
Quality-efficiency across three VLMs
Figure. Vision–language quality–efficiency across three VLMs — CoCurve leads every Avg₇ block along the pruning sweep.

Why It Works · The Edges Are Decisive

The cross-module edge is the ingredient

On Llama-3.1-8B-Instruct at 20%, a diagonal-only variant (node saliency alone) reaches 13.1 perplexity; adding the co-pruning edges lowers it to 12.9 and lifts Avg₁₂ by +2.0 points. At 30% the gap widens — diagonal-only 26.0 → CoCurve 21.6.

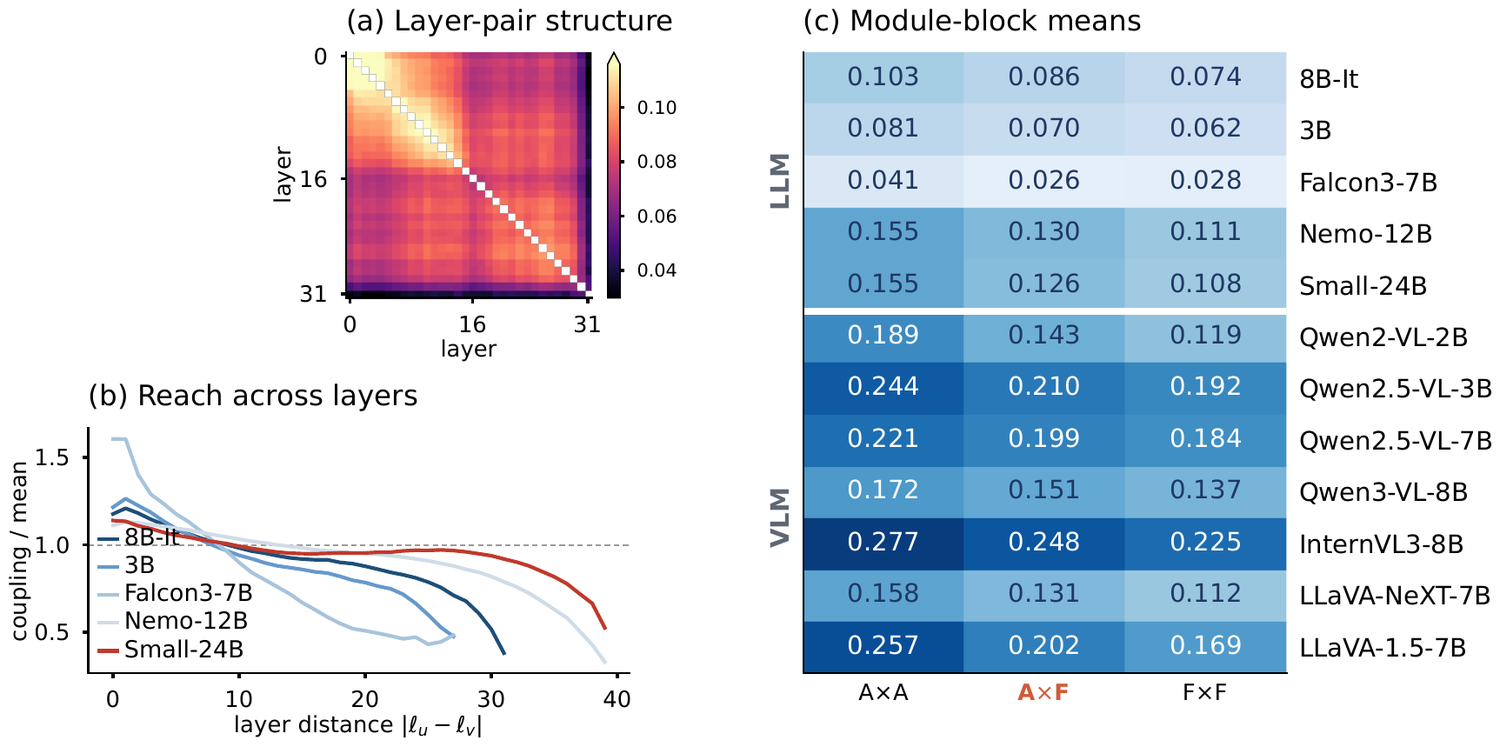
It is specifically the attention↔FFN cross-block that is load-bearing: across five language models the mean attention–FFN edge magnitude is 0.74–0.98× the within-module mean, and matched low-saliency, high-coupling (“bridge”) removals degrade 19/20 capability groups by up to 23.7 points.

An a-priori rule for when edges help

The edge bonus grows as FFN channels become less redundant — a quantity read from the calibration matrix alone, before any benchmark. Low-redundancy models (Falcon3-7B 0.028, Llama-3.1-8B 0.074) take full edges (λ=1); higher-redundancy ones (Qwen2.5-14B 0.198) damp toward the OBD diagonal.

So λ is chosen without labels, and the method degrades gracefully to a strong node-saliency selector exactly where edges would not help.
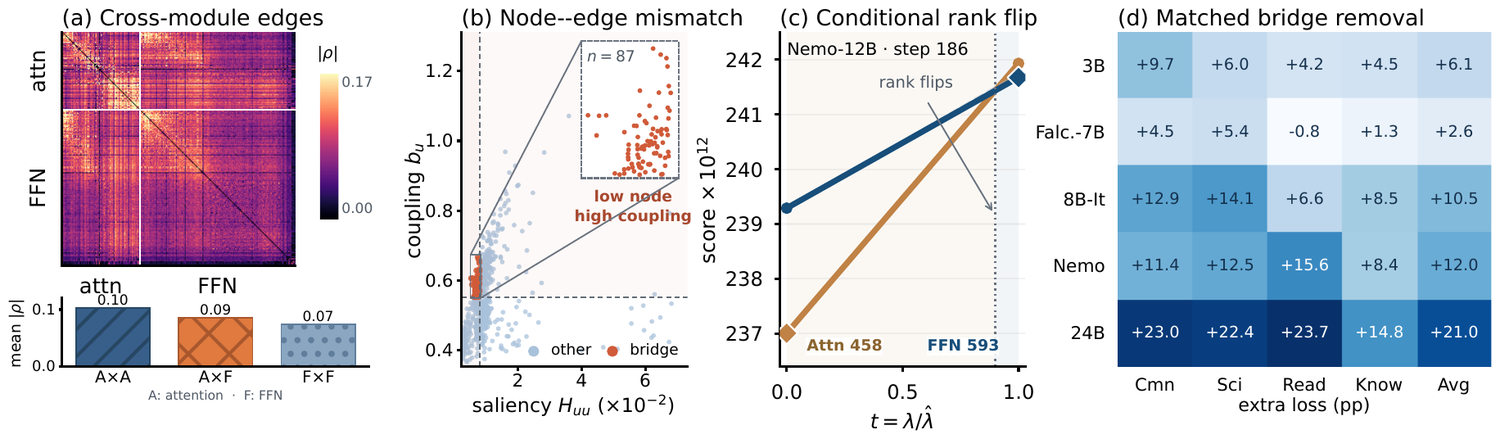
Cross-module edges, node-edge mismatch, conditional rank flip, matched bridge removal
Figure. Edges connect structure, decisions, and behavior — (a) cross-module co-pruning edges are real; (b) node saliency mismatches edge importance; (c) conditioning flips the node-only ranking; (d) matched bridge removal degrades 19/20 capability groups by up to 23.7 points.
Layer-pair structure, coupling reach, module-block means
Figure. Anatomy of H — (a) layer-pair structure, (b) coupling reach across layer distance, (c) attention/FFN module-block means across models.
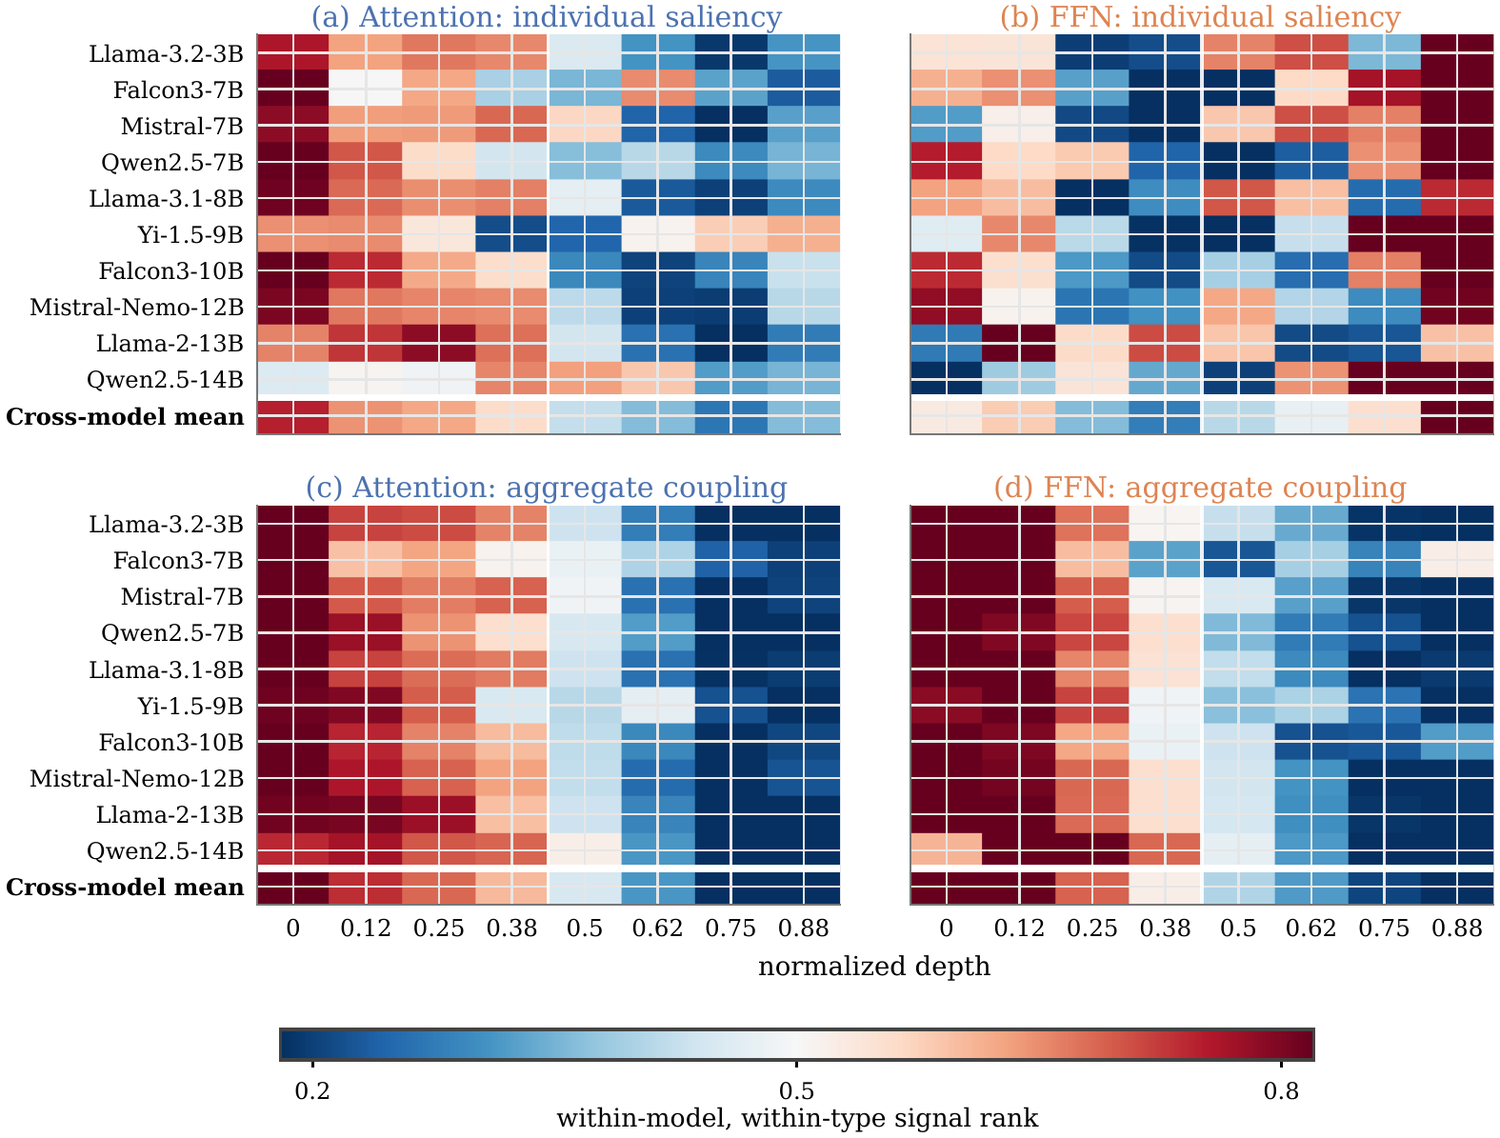
Attention and FFN saliency and coupling across depth, cross-model
Figure. Individual saliency and aggregate coupling for attention and FFN across normalized depth, ranked within model and type — organized, cross-model structure a node-only score is blind to.

Ablation — Llama-3.1-8B-Instruct (WikiText ↓ / Avg₁₂ ↑)

VariantρWiki ↓Avg₁₂ ↑
Dense—6.465.2
Diagonal only (λ=0)20%13.155.1
Full CoCurve (λ=1)20%12.956.0
Diagonal only (λ=0)30%26.048.7
Full CoCurve (λ=1)30%21.649.0

Module choice matters too: on Falcon3-7B, attention-only pruning collapses (WikiText 851) while FFN-only stays at 7.07 — CoCurve's shared budget trades across modules automatically.
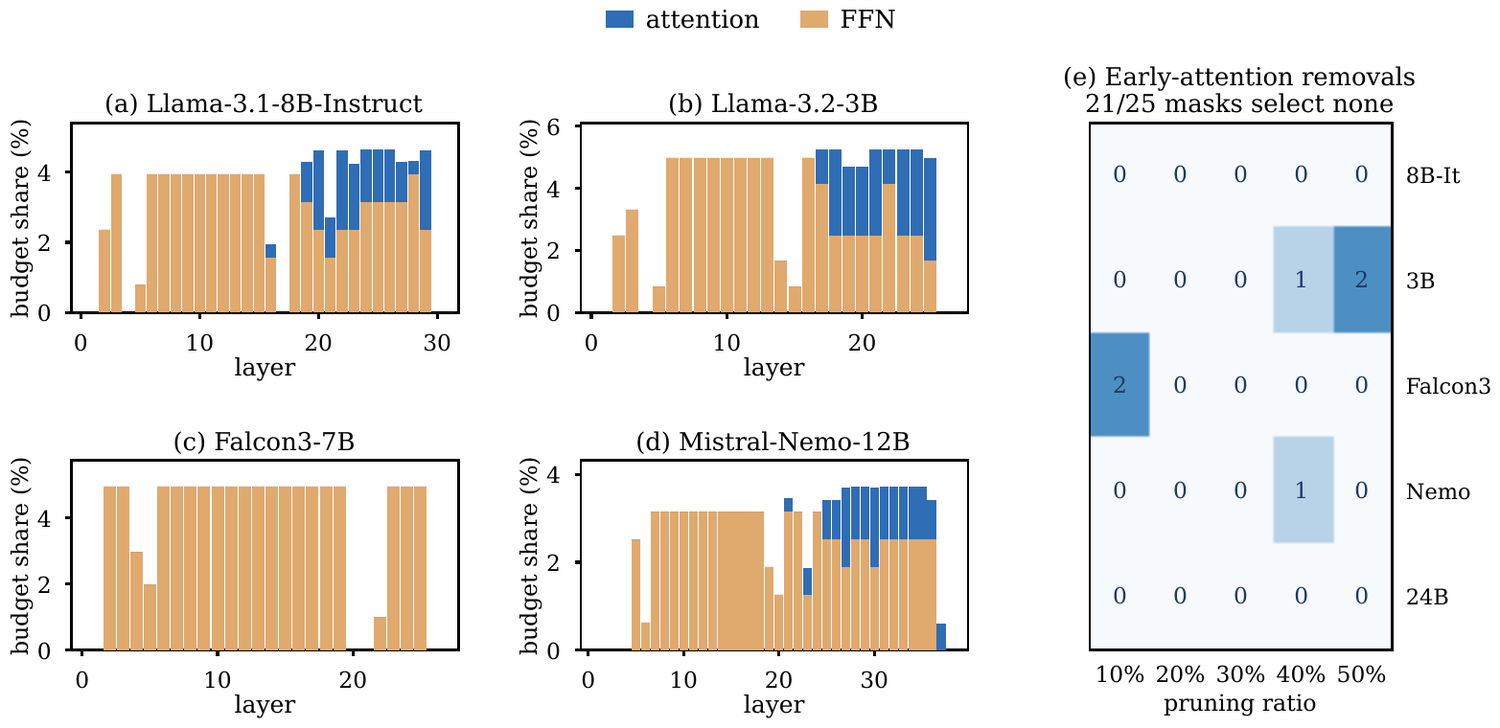
Per-layer attention vs FFN budget allocation
Figure. The per-layer attention-vs-FFN budget CoCurve allocates directly from the shared objective — early-attention removals are selected only sparingly.

Efficiency & Calibration

Real removal — accuracy at a given speedup

  • Physical slicing yields real speedups that grow with the budget: on Llama-3.1-8B-Instruct prefill rises 1.21× → 1.58× and peak memory falls to 0.83× → 0.59× dense as ρ goes 20% → 50%.
  • At 20% across 3B–12B: prefill +17–21%, peak memory −16–17%, decode within 5% (up to +9%).
  • The prefill band across matched-mask methods is narrow (1.167–1.233× at 20%), governed by the removed-parameter fraction — essentially method-independent. So the real discriminator is accuracy at a given speedup, where CoCurve wins.
  • Every reported speedup reflects real physical removal — slicing is bit-identical to masking, verified on held-out batches.

Honest scope

  • Fully evaluated across 6 LLMs (3B–70B) and 3 VLMs. Without recovery, selection-only methods degrade super-linearly beyond ~30%, so CoCurve targets moderate compression.
  • A lightweight LoRA recovery extends the lead through 50% pruning — the 8B checkpoint regains 10.8 Avg₁₂ points.
  • The edge bonus is architecture-dependent; on high-redundancy families it damps to a strong OBD diagonal — a graceful fallback, not a failure.
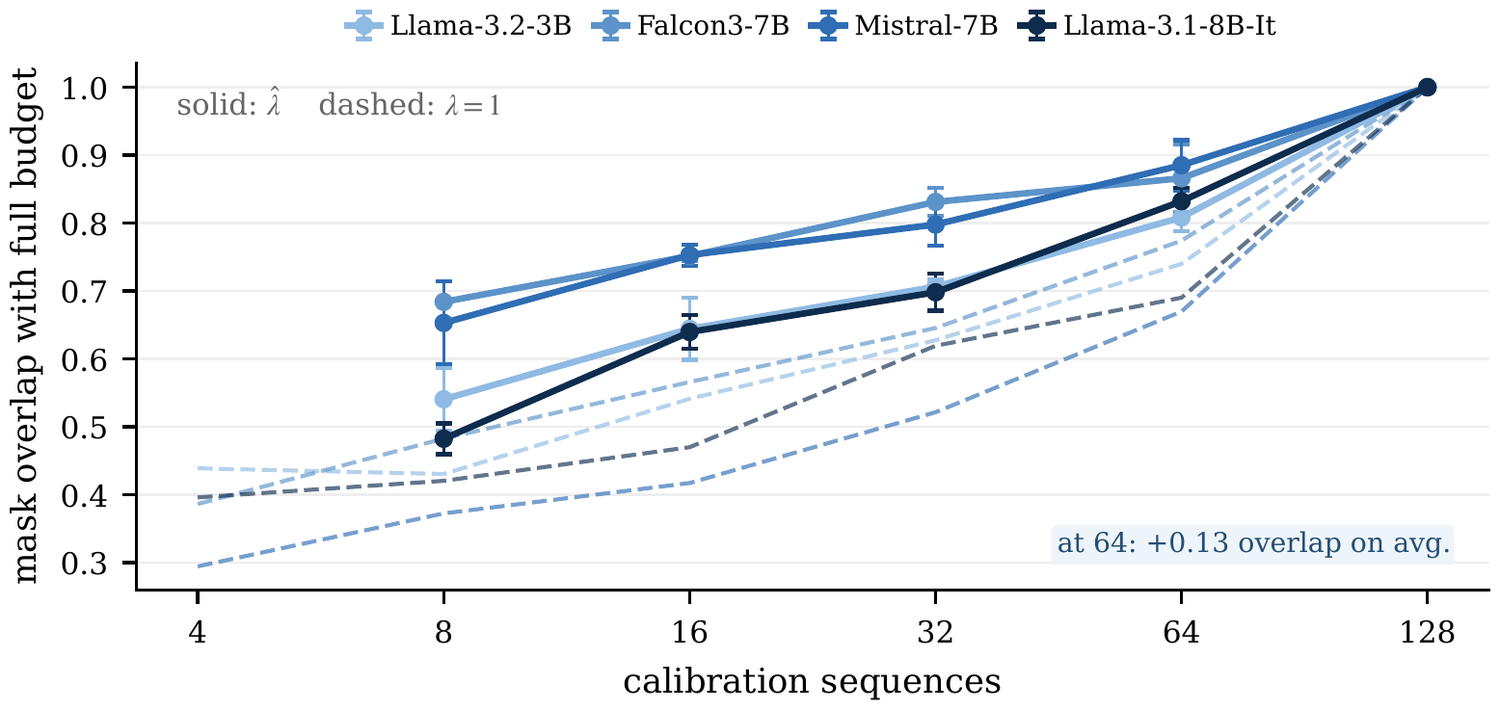
Mask overlap with full budget vs calibration sequences
Figure. Selected masks stabilize with calibration size — by 64 sequences the mask overlaps the full-budget mask by +0.13 on average.
Perplexity and average accuracy across calibration sizes
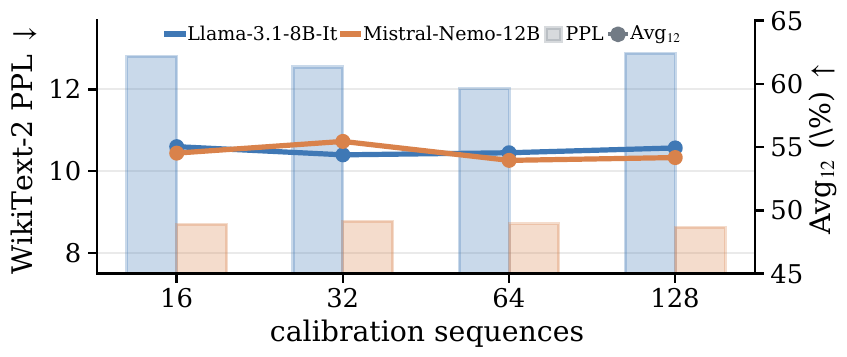
Figure. Quality is essentially flat across calibration sizes from 16–128 sequences — CoCurve needs only a small, cheap calibration set.

Resources

Code

Reference implementation and one-command reproduction on GitHub.

Tutorial

A narrated, animated ~7-minute video tour — the coupling problem, the co-pruning curvature edges, and the results, built for a general audience.